Sriram Sanka

Databases | Cloud | Infrastructure | Security |

Posts Tagged ‘AWS’

AWS License Manager Deep Dive: Architecture, Security, Cost & Operations

Posted by Sriram Sanka on August 18, 2026

AWS License Manager architecture diagram
AWS License Manager architecture and operating-boundary overview.

AWS License Manager provides software license inventory, entitlements, usage controls, and vendor integration. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Software license inventory, entitlements, usage controls, and vendor integration
Primary operating unit: account, resource, policy evaluation, signal, change, or recommendation
Decision boundary: organization design, evidence, delegated administration, quotas, and operator access
Field note 01

The short version

AWS License Manager provides software license inventory, entitlements, usage controls, and vendor integration. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Adopt AWS License Manager when software license inventory, entitlements, usage controls, and vendor integration is an enduring workload requirement and the managed boundary removes work your organization does not need to differentiate. The service decision should be based on measurable behavior and ownership, not catalog breadth. A proof must exercise the hardest integration, the most credible failure, the security boundary, and the dominant unit-cost driver before the design is standardized.

The practical decision is not whether AWS License Manager is powerful. It is whether its operating model fits the system and the team. It is best suited to workloads that explicitly need software license inventory, entitlements, usage controls, and vendor integration; teams prepared to operate the surrounding identity, network, data, telemetry, delivery, and recovery controls; and platforms that can measure each account, resource, policy evaluation, signal, change, or recommendation. It is usually a poor fit for systems whose requirement can be met by a narrower native control, external platform, or disciplined infrastructure code; teams without an accountable service owner; or designs that cannot explain organization design, evidence, delegated administration, quotas, and operator access before production traffic arrives. That boundary should be written into the architecture decision so later growth does not turn an intentional choice into accidental lock-in.

Field note 02

Build the right mental model

Think of AWS License Manager as a managed control plane around each account, resource, policy evaluation, signal, change, or recommendation. The service accepts desired state, policy, configuration, or workload input, then coordinates AWS-owned infrastructure to deliver software license inventory, entitlements, usage controls, and vendor integration. The exact managed boundary varies by feature and region, but the architectural pattern is stable: management APIs change configuration, resource policies and IAM decide who may act, service endpoints carry production work, telemetry reports selected behavior, and quotas bound how quickly the system can grow. Customer data, application correctness, access choices, downstream dependencies, and business recovery remain customer concerns even when infrastructure replacement is automated.

A production implementation begins with account and region placement, least-privilege administrative and runtime roles, network reachability, encryption ownership, quotas, logging, tags, and configuration expressed as code. For AWS License Manager, define the authoritative resource model, immutable or versioned deployment unit, and the path from a reviewed change to active service behavior. Identify asynchronous operations, eventual consistency, retry semantics, deletion behavior, and every resource created indirectly. Record which actions are safe to repeat, which require a change window, and which can cause data loss or customer-visible interruption.

Separate the control plane from the data plane in both design and incident response. The control plane creates configuration and desired state; the data plane carries production work. A deployment API succeeding does not prove that traffic, jobs, or events are healthy. Conversely, a transient control-plane problem should not automatically stop already-running work. Document which APIs are needed during steady state, which are needed only for change, and which dependencies sit on the critical request path.

Make ownership boundaries visible. Identity, network reachability, encryption keys, artifacts, telemetry, quotas, and billing dimensions frequently belong to different teams. A service can be technically managed while the surrounding system remains unmanaged. Name an owner for the application, the platform configuration, the data, the recovery procedure, and the cost model. That simple map prevents the most common failure mode in cloud programs: assuming an abstraction transferred a responsibility that it only moved.

Field note 03

Where it earns its keep

The strongest AWS License Manager architectures begin with a workload whose constraints align with the service. The following patterns are starting points, not product marketing categories. Each still needs an explicit data model, failure model, and ownership model.

Do not choose a cloud service from the deployment demo alone. A demo proves that the happy path exists; an architecture decision must explain day-two change, degraded dependencies, recovery, security evidence, and cost under real load. For AWS License Manager, those questions reveal whether the service removes undifferentiated work or merely postpones it.

  • Primary production pattern: Use AWS License Manager where software license inventory, entitlements, usage controls, and vendor integration is on the critical path and the team can own the surrounding controls.
  • Governed shared capability: A platform team can package identity, policy, telemetry, cost allocation, and recovery defaults for multiple consumers.
  • Migration or modernization: Adopt the managed boundary incrementally while preserving data validation, rollback, and an explicit exit path.
Field note 04

Architecture moves that age well

A useful reference architecture is a set of constraints with reasons, not a diagram crowded with service icons. Start with the moves below, assign an owner to each, and encode the ones that can be enforced. Exceptions should include an expiration date and a test that proves why the normal path does not work.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

  • Define the authoritative AWS License Manager resource model and provision it from reviewed, versioned configuration.
  • Measure capacity, latency, failure, and cost per account, resource, policy evaluation, signal, change, or recommendation under production-shaped load.
  • Separate administrative, deployment, and runtime identities and centralize evidence outside the workload boundary.
  • Test restoration or replacement and document the requirement that would trigger an exit from AWS License Manager.
Field note 05

Scaling and performance

AWS License Manager capacity should be planned from the arrival rate and shape of each account, resource, policy evaluation, signal, change, or recommendation, not from an average utilization graph. Model steady load, bursts, backlog, object or payload size, concurrency, retention, dependency ceilings, and regional quotas. Separate a control-plane request being accepted from capacity becoming usable. Measure provisioning, warm-up, propagation, and recovery time. Where scaling is automatic, set guardrails that protect downstream systems and budgets. Where it is manual, define leading indicators and enough headroom for failure plus deployment overlap.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

Performance tuning must preserve correctness. Optimize the slowest meaningful business path, verify the change against a representative distribution, and watch for work displaced into queues, retries, caches, or operators. With AWS License Manager, a lower service-level latency can still create a worse system if downstream saturation, recovery backlog, or cost per completed transaction rises. Keep load-test artifacts and capacity assumptions versioned beside the architecture.

Field note 06

Security and governance

Secure AWS License Manager through explicit trust boundaries. Separate human administration, deployment automation, and runtime access; narrow actions and resources; use short-lived credentials; and apply organization guardrails to public exposure, deletion, cross-account sharing, and encryption changes. Protect data in transit and at rest with a documented key model. Send audit and security evidence to a boundary the workload cannot rewrite. Validate untrusted names, payloads, metadata, and configuration even when they arrive through an AWS integration. Treat service-linked roles, resource policies, grants, endpoints, and delegated administration as production code.

Use least privilege as an engineering process, not a one-time IAM document. Begin with separate human, deployment, and runtime identities. Observe required actions, narrow resources and conditions, and add explicit organization guardrails for high-impact operations. Encrypt data in transit and at rest, but also design key ownership, rotation, deletion protection, and break-glass access. Centralize audit records in an account and storage boundary that a compromised workload cannot rewrite.

Threat-model AWS License Manager across four surfaces: the management API, the workload’s runtime identity, the network and event inputs that reach it, and the software or configuration artifact that is deployed. Add the data stores and observability pipeline as separate trust boundaries. Preventive controls reduce the reachable state space; detective controls shorten time to evidence; recovery controls make destructive events survivable. A mature design has all three and tests them independently.

Governance should make the secure path faster. Provide approved modules, narrowly scoped roles, standard encryption and logging defaults, ownership tags, and automated evidence. Block dangerous configurations at the organization or pipeline boundary when the intent is unambiguous. Leave application teams enough room to tune the workload without letting every team invent identity, ingress, logging, and incident access from scratch.

Field note 07

Reliability and recovery

Reliability for AWS License Manager is the ability to preserve the intended business outcome when a zone, region, dependency, credential, quota, configuration, or operator action fails. Determine which components are regional or zonal and which state is durable, replicated, restorable, or reproducible. Set recovery-time and recovery-point objectives, then build the smallest mechanism that meets them. Test throttling, unavailable capacity, partial completion, duplicate delivery, stale configuration, corrupted input, telemetry loss, and recovery into an isolated environment. A multi-AZ service does not make a single-region or single-account application automatically recoverable.

Define failure in business terms before selecting a recovery mechanism. Availability, durability, recovery time, and recovery point are different objectives. Multi-zone placement improves some infrastructure failures but does not repair corrupt deployments or deleted data. Backups address some data events but do not guarantee a runnable application. Use layered controls: health-based replacement, redundancy, deployment rollback, data protection, quota monitoring, and a rehearsed regional or organizational recovery path where the business requires one.

Write failure-mode tests for AWS License Manager before the first serious incident. Include unavailable capacity, throttled control APIs, expired credentials, bad configuration, dependency timeout, partial deployment, telemetry loss, and operator error. Test what happens to in-flight work, how the system detects the condition, who is paged, and how replay or rollback avoids duplicate effects. Recovery time measured in a game day is more credible than recovery time copied from a diagram.

Keep the recovery path simpler than the primary path. If restoration depends on the same identity, network, artifact repository, region, or specialist that the incident removed, it is not independent. Store runbooks where responders can reach them, pre-authorize narrowly scoped emergency actions, and verify backups by restoring into an isolated environment. Record the achieved recovery point and time so business owners can compare evidence with policy.

Field note 08

Cost and capacity economics

Model AWS License Manager with a unit that finance and engineering both understand: cost per account, resource, policy evaluation, signal, change, or recommendation. Include baseline resources, request or execution charges, storage and retention, logs, network transfer, cross-zone or cross-region movement, encryption and security services, backups, support, licenses, and operator time. Build expected and stress scenarios, attach owners to long-lived resources, and alarm on abnormal unit cost. Remove waste and rightsize before purchasing commitments. Preserve the capacity and retention margins required by the reliability objective instead of treating every idle byte or spare unit as waste.

Evaluate unit economics at the level customers consume: cost per request, job, simulation, tenant, build, or environment. Tagging helps allocation, but architecture determines most spend. Include idle baseline, burst premium, storage growth, log retention, data transfer, support, licenses, and operator time. Rate discounts should follow rightsizing and workload-shape work. A commitment applied to the wrong baseline converts an optimization opportunity into a contract.

Create a cost model for AWS License Manager with a low, expected, and stress scenario. Tie every variable to a measurable workload characteristic and identify which team can influence it. Alarm on anomalous unit cost as well as total spend; total spend naturally rises with successful products, while unit cost exposes architectural drift. Review unused capacity and retained artifacts on a schedule, and give every long-lived resource an owner and lifecycle policy.

Optimization should preserve reliability margins. Removing all idle capacity, shortening every retention period, or consolidating every boundary may lower a spreadsheet while increasing incident probability and recovery time. Price the resilience requirement explicitly. Then apply the least risky lever first: eliminate waste, rightsize, improve utilization, reduce unnecessary transfer, select the correct purchasing model, and only then make longer commitments.

Field note 09

Operating it in production

Operate AWS License Manager as a product with a named owner, versioned modules, approved defaults, dashboards, runbooks, lifecycle reviews, and an exception process. Monitor customer symptoms and service saturation together. Track change success, quota headroom, access exceptions, failed operations, recovery evidence, spend, and AWS lifecycle announcements. Provide developers a paved contract that hides repetitive configuration without hiding state. Review incidents and near misses monthly until routine replacement, rollback, replay, access recertification, and recovery are boring and evidenced.

Treat configuration as versioned product code. Changes should pass static checks, policy checks, integration tests, and an environment that resembles production. Promote the same artifact; do not rebuild it differently at every stage. Prefer gradual exposure, observable health gates, and automated rollback for reversible changes. For irreversible data or identity changes, use expansion-and-contraction patterns and explicit checkpoints. Record who changed what, why, and which measured signal declared the change safe.

Build one operational view that links AWS License Manager health to customer outcomes. Infrastructure metrics explain resources, application metrics explain behavior, traces explain selected paths, and logs provide detailed evidence. None is sufficient alone. Define symptom-based alerts around availability, latency, backlog, freshness, correctness, and saturation; route them to an accountable team; and attach the first diagnostic action. Remove alerts that never change a decision.

Run a monthly service review until the platform is boring. Examine incidents, near misses, failed changes, quota headroom, runtime or image lifecycle, cost per unit, access exceptions, recovery evidence, and support announcements. Convert repeated manual actions into automation only after the team understands the decision being automated. Good operations reduce surprise without hiding state from the people accountable for it.

Field note 10

Failure patterns to avoid

Most expensive mistakes are reasonable shortcuts that survived beyond their original context. Treat these risks as design-review prompts. Ask which control detects each condition, how quickly the team can recover, and whether the workload can be moved or reshaped before the risk becomes a constraint.

A risk register is useful only when it changes action. Give each item an owner, leading indicator, mitigation, and review date. If a risk is accepted, record the business reason. If it is mitigated, test the mitigation. If it is transferred to a managed service, verify the exact responsibility that moved instead of assuming the service name moved all of it.

  • The team assumes AWS License Manager transfers application, data, or recovery responsibility that remains with the customer.
  • Automatic scale reaches a quota or overwhelms a downstream dependency before alerts explain the symptom.
  • Manual console changes create drift from the reviewed configuration and weaken incident reconstruction.
  • A lifecycle, pricing, regional, or feature change is discovered only after the architecture depends on it.
Field note 11

Alternatives and the decision

Compare AWS License Manager with a narrower native control, external platform, or disciplined infrastructure code using the same workload, security assumptions, recovery target, and cost horizon. A managed service can reduce infrastructure labor while increasing product-specific policy, integration, and exit work. Portability of data formats or APIs does not guarantee portability of identity, monitoring, automation, or operating knowledge. The strongest decision states what AWS License Manager uniquely contributes, what the organization still owns, and which changed requirement would trigger a different platform.

AWS License Manager is a sound choice when the requirement for software license inventory, entitlements, usage controls, and vendor integration is concrete, the managed boundary is understood, and the team can operate the complete system around it. Start with a production-shaped proof, constrain variation, automate safe defaults, and retain an exit path through portable data, documented configuration, and reproducible artifacts. If the service is marked preview, changing, renamed, or retired, treat availability and lifecycle constraints as first-class architecture inputs rather than documentation footnotes.

Use a short proof of architecture when uncertainty is material. Test the hardest requirement, the most important failure mode, and the expected cost driver—not another hello-world deployment. Compare AWS License Manager with the strongest alternative using the same workload and evidence. Record the decision, rejected options, assumptions, migration trigger, and date for review. Architecture remains healthy when a future team can understand both why the choice was correct and which changed fact would make it wrong.

Field note 12

A pragmatic 90-day adoption plan

Days 1–15: define the workload and responsibility map. Capture traffic or job shape, data sensitivity, availability and recovery objectives, latency, unit economics, dependencies, regional constraints, and team ownership. Build a thin threat model and request quota changes early. Select one representative path for the proof, not the easiest path. Establish a clean account, identity, network, artifact, encryption, and logging baseline before application convenience creates permanent exceptions.

Days 16–35: implement a production-shaped walking skeleton on AWS License Manager. Provision it from code, deploy an immutable artifact, integrate one real dependency, emit structured telemetry, and prove that a new team member can reproduce the environment. Exercise duplicate work, bad input, dependency timeout, and lost capacity. Measure cold and warm behavior where relevant, saturation, recovery backlog, and cost per successful business unit.

Days 36–60: harden delivery and recovery. Add policy checks, staged promotion, rollback or replacement, least-privilege runtime identity, secret rotation, data protection, retention, and symptom-based alerts. Restore from backup or recreate from artifacts in an isolated environment. Run a game day that includes an operator mistake and a compromised credential. Convert the findings into platform defaults and owned backlog items rather than a slide deck.

Days 61–90: place controlled production load on the service, review evidence with security, finance, and operations, and compare observed behavior with the original decision. Publish a paved-road module, dashboard, runbook, and exception process. Set capacity and cost review thresholds. Finally, write the exit criteria: the scale, feature, compliance need, economics, or organizational change that would trigger a move away from AWS License Manager. A reversible decision is easier to make well.

Posted in Management & Governance | Tagged: , , , , , , , , , , , | Leave a Comment »

AWS Launch Wizard Deep Dive: Architecture, Security, Cost & Operations

Posted by Sriram Sanka on August 18, 2026

AWS Launch Wizard architecture diagram
AWS Launch Wizard architecture and operating-boundary overview.

AWS Launch Wizard provides guided sizing and deployment of complex enterprise applications. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Guided sizing and deployment of complex enterprise applications
Primary operating unit: account, resource, policy evaluation, signal, change, or recommendation
Decision boundary: organization design, evidence, delegated administration, quotas, and operator access
Field note 01

The short version

AWS Launch Wizard provides guided sizing and deployment of complex enterprise applications. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Adopt AWS Launch Wizard when guided sizing and deployment of complex enterprise applications is an enduring workload requirement and the managed boundary removes work your organization does not need to differentiate. The service decision should be based on measurable behavior and ownership, not catalog breadth. A proof must exercise the hardest integration, the most credible failure, the security boundary, and the dominant unit-cost driver before the design is standardized.

The practical decision is not whether AWS Launch Wizard is powerful. It is whether its operating model fits the system and the team. It is best suited to workloads that explicitly need guided sizing and deployment of complex enterprise applications; teams prepared to operate the surrounding identity, network, data, telemetry, delivery, and recovery controls; and platforms that can measure each account, resource, policy evaluation, signal, change, or recommendation. It is usually a poor fit for systems whose requirement can be met by a narrower native control, external platform, or disciplined infrastructure code; teams without an accountable service owner; or designs that cannot explain organization design, evidence, delegated administration, quotas, and operator access before production traffic arrives. That boundary should be written into the architecture decision so later growth does not turn an intentional choice into accidental lock-in.

Field note 02

Build the right mental model

Think of AWS Launch Wizard as a managed control plane around each account, resource, policy evaluation, signal, change, or recommendation. The service accepts desired state, policy, configuration, or workload input, then coordinates AWS-owned infrastructure to deliver guided sizing and deployment of complex enterprise applications. The exact managed boundary varies by feature and region, but the architectural pattern is stable: management APIs change configuration, resource policies and IAM decide who may act, service endpoints carry production work, telemetry reports selected behavior, and quotas bound how quickly the system can grow. Customer data, application correctness, access choices, downstream dependencies, and business recovery remain customer concerns even when infrastructure replacement is automated.

A production implementation begins with account and region placement, least-privilege administrative and runtime roles, network reachability, encryption ownership, quotas, logging, tags, and configuration expressed as code. For AWS Launch Wizard, define the authoritative resource model, immutable or versioned deployment unit, and the path from a reviewed change to active service behavior. Identify asynchronous operations, eventual consistency, retry semantics, deletion behavior, and every resource created indirectly. Record which actions are safe to repeat, which require a change window, and which can cause data loss or customer-visible interruption.

Separate the control plane from the data plane in both design and incident response. The control plane creates configuration and desired state; the data plane carries production work. A deployment API succeeding does not prove that traffic, jobs, or events are healthy. Conversely, a transient control-plane problem should not automatically stop already-running work. Document which APIs are needed during steady state, which are needed only for change, and which dependencies sit on the critical request path.

Make ownership boundaries visible. Identity, network reachability, encryption keys, artifacts, telemetry, quotas, and billing dimensions frequently belong to different teams. A service can be technically managed while the surrounding system remains unmanaged. Name an owner for the application, the platform configuration, the data, the recovery procedure, and the cost model. That simple map prevents the most common failure mode in cloud programs: assuming an abstraction transferred a responsibility that it only moved.

Field note 03

Where it earns its keep

The strongest AWS Launch Wizard architectures begin with a workload whose constraints align with the service. The following patterns are starting points, not product marketing categories. Each still needs an explicit data model, failure model, and ownership model.

Do not choose a cloud service from the deployment demo alone. A demo proves that the happy path exists; an architecture decision must explain day-two change, degraded dependencies, recovery, security evidence, and cost under real load. For AWS Launch Wizard, those questions reveal whether the service removes undifferentiated work or merely postpones it.

  • Primary production pattern: Use AWS Launch Wizard where guided sizing and deployment of complex enterprise applications is on the critical path and the team can own the surrounding controls.
  • Governed shared capability: A platform team can package identity, policy, telemetry, cost allocation, and recovery defaults for multiple consumers.
  • Migration or modernization: Adopt the managed boundary incrementally while preserving data validation, rollback, and an explicit exit path.
Field note 04

Architecture moves that age well

A useful reference architecture is a set of constraints with reasons, not a diagram crowded with service icons. Start with the moves below, assign an owner to each, and encode the ones that can be enforced. Exceptions should include an expiration date and a test that proves why the normal path does not work.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

  • Define the authoritative AWS Launch Wizard resource model and provision it from reviewed, versioned configuration.
  • Measure capacity, latency, failure, and cost per account, resource, policy evaluation, signal, change, or recommendation under production-shaped load.
  • Separate administrative, deployment, and runtime identities and centralize evidence outside the workload boundary.
  • Test restoration or replacement and document the requirement that would trigger an exit from AWS Launch Wizard.
Field note 05

Scaling and performance

AWS Launch Wizard capacity should be planned from the arrival rate and shape of each account, resource, policy evaluation, signal, change, or recommendation, not from an average utilization graph. Model steady load, bursts, backlog, object or payload size, concurrency, retention, dependency ceilings, and regional quotas. Separate a control-plane request being accepted from capacity becoming usable. Measure provisioning, warm-up, propagation, and recovery time. Where scaling is automatic, set guardrails that protect downstream systems and budgets. Where it is manual, define leading indicators and enough headroom for failure plus deployment overlap.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

Performance tuning must preserve correctness. Optimize the slowest meaningful business path, verify the change against a representative distribution, and watch for work displaced into queues, retries, caches, or operators. With AWS Launch Wizard, a lower service-level latency can still create a worse system if downstream saturation, recovery backlog, or cost per completed transaction rises. Keep load-test artifacts and capacity assumptions versioned beside the architecture.

Field note 06

Security and governance

Secure AWS Launch Wizard through explicit trust boundaries. Separate human administration, deployment automation, and runtime access; narrow actions and resources; use short-lived credentials; and apply organization guardrails to public exposure, deletion, cross-account sharing, and encryption changes. Protect data in transit and at rest with a documented key model. Send audit and security evidence to a boundary the workload cannot rewrite. Validate untrusted names, payloads, metadata, and configuration even when they arrive through an AWS integration. Treat service-linked roles, resource policies, grants, endpoints, and delegated administration as production code.

Use least privilege as an engineering process, not a one-time IAM document. Begin with separate human, deployment, and runtime identities. Observe required actions, narrow resources and conditions, and add explicit organization guardrails for high-impact operations. Encrypt data in transit and at rest, but also design key ownership, rotation, deletion protection, and break-glass access. Centralize audit records in an account and storage boundary that a compromised workload cannot rewrite.

Threat-model AWS Launch Wizard across four surfaces: the management API, the workload’s runtime identity, the network and event inputs that reach it, and the software or configuration artifact that is deployed. Add the data stores and observability pipeline as separate trust boundaries. Preventive controls reduce the reachable state space; detective controls shorten time to evidence; recovery controls make destructive events survivable. A mature design has all three and tests them independently.

Governance should make the secure path faster. Provide approved modules, narrowly scoped roles, standard encryption and logging defaults, ownership tags, and automated evidence. Block dangerous configurations at the organization or pipeline boundary when the intent is unambiguous. Leave application teams enough room to tune the workload without letting every team invent identity, ingress, logging, and incident access from scratch.

Field note 07

Reliability and recovery

Reliability for AWS Launch Wizard is the ability to preserve the intended business outcome when a zone, region, dependency, credential, quota, configuration, or operator action fails. Determine which components are regional or zonal and which state is durable, replicated, restorable, or reproducible. Set recovery-time and recovery-point objectives, then build the smallest mechanism that meets them. Test throttling, unavailable capacity, partial completion, duplicate delivery, stale configuration, corrupted input, telemetry loss, and recovery into an isolated environment. A multi-AZ service does not make a single-region or single-account application automatically recoverable.

Define failure in business terms before selecting a recovery mechanism. Availability, durability, recovery time, and recovery point are different objectives. Multi-zone placement improves some infrastructure failures but does not repair corrupt deployments or deleted data. Backups address some data events but do not guarantee a runnable application. Use layered controls: health-based replacement, redundancy, deployment rollback, data protection, quota monitoring, and a rehearsed regional or organizational recovery path where the business requires one.

Write failure-mode tests for AWS Launch Wizard before the first serious incident. Include unavailable capacity, throttled control APIs, expired credentials, bad configuration, dependency timeout, partial deployment, telemetry loss, and operator error. Test what happens to in-flight work, how the system detects the condition, who is paged, and how replay or rollback avoids duplicate effects. Recovery time measured in a game day is more credible than recovery time copied from a diagram.

Keep the recovery path simpler than the primary path. If restoration depends on the same identity, network, artifact repository, region, or specialist that the incident removed, it is not independent. Store runbooks where responders can reach them, pre-authorize narrowly scoped emergency actions, and verify backups by restoring into an isolated environment. Record the achieved recovery point and time so business owners can compare evidence with policy.

Field note 08

Cost and capacity economics

Model AWS Launch Wizard with a unit that finance and engineering both understand: cost per account, resource, policy evaluation, signal, change, or recommendation. Include baseline resources, request or execution charges, storage and retention, logs, network transfer, cross-zone or cross-region movement, encryption and security services, backups, support, licenses, and operator time. Build expected and stress scenarios, attach owners to long-lived resources, and alarm on abnormal unit cost. Remove waste and rightsize before purchasing commitments. Preserve the capacity and retention margins required by the reliability objective instead of treating every idle byte or spare unit as waste.

Evaluate unit economics at the level customers consume: cost per request, job, simulation, tenant, build, or environment. Tagging helps allocation, but architecture determines most spend. Include idle baseline, burst premium, storage growth, log retention, data transfer, support, licenses, and operator time. Rate discounts should follow rightsizing and workload-shape work. A commitment applied to the wrong baseline converts an optimization opportunity into a contract.

Create a cost model for AWS Launch Wizard with a low, expected, and stress scenario. Tie every variable to a measurable workload characteristic and identify which team can influence it. Alarm on anomalous unit cost as well as total spend; total spend naturally rises with successful products, while unit cost exposes architectural drift. Review unused capacity and retained artifacts on a schedule, and give every long-lived resource an owner and lifecycle policy.

Optimization should preserve reliability margins. Removing all idle capacity, shortening every retention period, or consolidating every boundary may lower a spreadsheet while increasing incident probability and recovery time. Price the resilience requirement explicitly. Then apply the least risky lever first: eliminate waste, rightsize, improve utilization, reduce unnecessary transfer, select the correct purchasing model, and only then make longer commitments.

Field note 09

Operating it in production

Operate AWS Launch Wizard as a product with a named owner, versioned modules, approved defaults, dashboards, runbooks, lifecycle reviews, and an exception process. Monitor customer symptoms and service saturation together. Track change success, quota headroom, access exceptions, failed operations, recovery evidence, spend, and AWS lifecycle announcements. Provide developers a paved contract that hides repetitive configuration without hiding state. Review incidents and near misses monthly until routine replacement, rollback, replay, access recertification, and recovery are boring and evidenced.

Treat configuration as versioned product code. Changes should pass static checks, policy checks, integration tests, and an environment that resembles production. Promote the same artifact; do not rebuild it differently at every stage. Prefer gradual exposure, observable health gates, and automated rollback for reversible changes. For irreversible data or identity changes, use expansion-and-contraction patterns and explicit checkpoints. Record who changed what, why, and which measured signal declared the change safe.

Build one operational view that links AWS Launch Wizard health to customer outcomes. Infrastructure metrics explain resources, application metrics explain behavior, traces explain selected paths, and logs provide detailed evidence. None is sufficient alone. Define symptom-based alerts around availability, latency, backlog, freshness, correctness, and saturation; route them to an accountable team; and attach the first diagnostic action. Remove alerts that never change a decision.

Run a monthly service review until the platform is boring. Examine incidents, near misses, failed changes, quota headroom, runtime or image lifecycle, cost per unit, access exceptions, recovery evidence, and support announcements. Convert repeated manual actions into automation only after the team understands the decision being automated. Good operations reduce surprise without hiding state from the people accountable for it.

Field note 10

Failure patterns to avoid

Most expensive mistakes are reasonable shortcuts that survived beyond their original context. Treat these risks as design-review prompts. Ask which control detects each condition, how quickly the team can recover, and whether the workload can be moved or reshaped before the risk becomes a constraint.

A risk register is useful only when it changes action. Give each item an owner, leading indicator, mitigation, and review date. If a risk is accepted, record the business reason. If it is mitigated, test the mitigation. If it is transferred to a managed service, verify the exact responsibility that moved instead of assuming the service name moved all of it.

  • The team assumes AWS Launch Wizard transfers application, data, or recovery responsibility that remains with the customer.
  • Automatic scale reaches a quota or overwhelms a downstream dependency before alerts explain the symptom.
  • Manual console changes create drift from the reviewed configuration and weaken incident reconstruction.
  • A lifecycle, pricing, regional, or feature change is discovered only after the architecture depends on it.
Field note 11

Alternatives and the decision

Compare AWS Launch Wizard with a narrower native control, external platform, or disciplined infrastructure code using the same workload, security assumptions, recovery target, and cost horizon. A managed service can reduce infrastructure labor while increasing product-specific policy, integration, and exit work. Portability of data formats or APIs does not guarantee portability of identity, monitoring, automation, or operating knowledge. The strongest decision states what AWS Launch Wizard uniquely contributes, what the organization still owns, and which changed requirement would trigger a different platform.

AWS Launch Wizard is a sound choice when the requirement for guided sizing and deployment of complex enterprise applications is concrete, the managed boundary is understood, and the team can operate the complete system around it. Start with a production-shaped proof, constrain variation, automate safe defaults, and retain an exit path through portable data, documented configuration, and reproducible artifacts. If the service is marked preview, changing, renamed, or retired, treat availability and lifecycle constraints as first-class architecture inputs rather than documentation footnotes.

Use a short proof of architecture when uncertainty is material. Test the hardest requirement, the most important failure mode, and the expected cost driver—not another hello-world deployment. Compare AWS Launch Wizard with the strongest alternative using the same workload and evidence. Record the decision, rejected options, assumptions, migration trigger, and date for review. Architecture remains healthy when a future team can understand both why the choice was correct and which changed fact would make it wrong.

Field note 12

A pragmatic 90-day adoption plan

Days 1–15: define the workload and responsibility map. Capture traffic or job shape, data sensitivity, availability and recovery objectives, latency, unit economics, dependencies, regional constraints, and team ownership. Build a thin threat model and request quota changes early. Select one representative path for the proof, not the easiest path. Establish a clean account, identity, network, artifact, encryption, and logging baseline before application convenience creates permanent exceptions.

Days 16–35: implement a production-shaped walking skeleton on AWS Launch Wizard. Provision it from code, deploy an immutable artifact, integrate one real dependency, emit structured telemetry, and prove that a new team member can reproduce the environment. Exercise duplicate work, bad input, dependency timeout, and lost capacity. Measure cold and warm behavior where relevant, saturation, recovery backlog, and cost per successful business unit.

Days 36–60: harden delivery and recovery. Add policy checks, staged promotion, rollback or replacement, least-privilege runtime identity, secret rotation, data protection, retention, and symptom-based alerts. Restore from backup or recreate from artifacts in an isolated environment. Run a game day that includes an operator mistake and a compromised credential. Convert the findings into platform defaults and owned backlog items rather than a slide deck.

Days 61–90: place controlled production load on the service, review evidence with security, finance, and operations, and compare observed behavior with the original decision. Publish a paved-road module, dashboard, runbook, and exception process. Set capacity and cost review thresholds. Finally, write the exit criteria: the scale, feature, compliance need, economics, or organizational change that would trigger a move away from AWS Launch Wizard. A reversible decision is easier to make well.

Posted in Management & Governance | Tagged: , , , , , , , , , , , | Leave a Comment »

AWS Lambda Deep Dive: Architecture, Security, Cost & Operations

Posted by Sriram Sanka on August 18, 2026

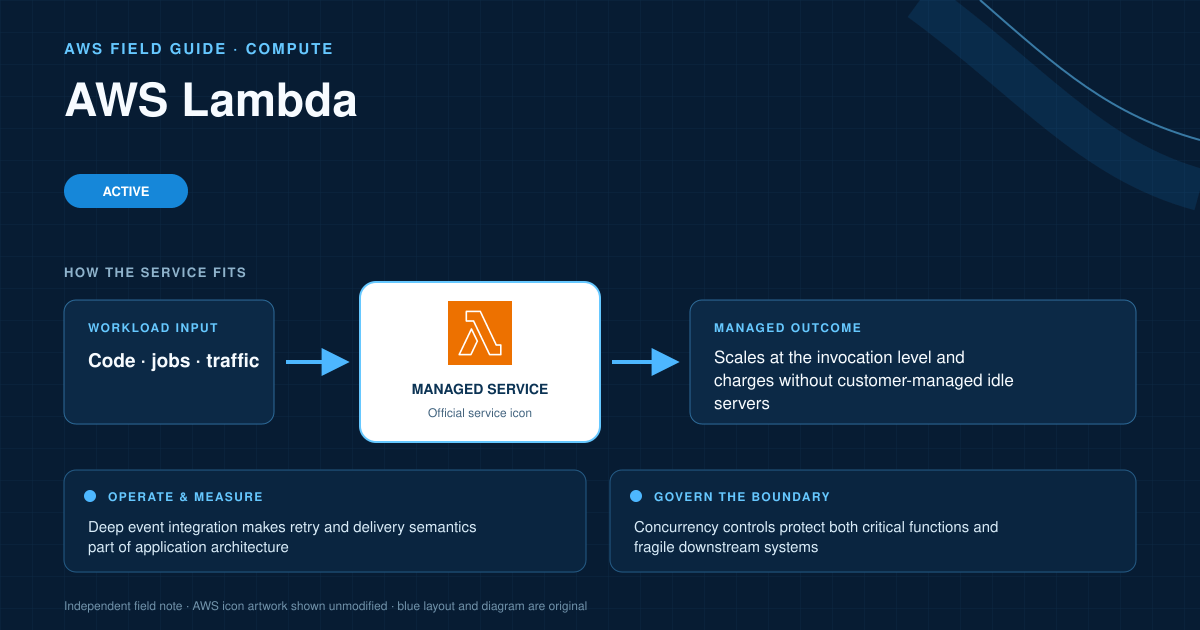
AWS Lambda architecture diagram
AWS Lambda architecture and operating-boundary overview.

Lambda runs code in response to requests and events while AWS manages execution environments, fleet capacity, and much of the availability work. The service turns compute into an invocation-level resource, but production success depends on understanding concurrency, retries, event semantics, downstream limits, and the lifecycle of an ephemeral runtime.

Scales at the invocation level and charges without customer-managed idle servers
Deep event integration makes retry and delivery semantics part of application architecture
Concurrency controls protect both critical functions and fragile downstream systems
Field note 01

The short version

Lambda runs code in response to requests and events while AWS manages execution environments, fleet capacity, and much of the availability work. The service turns compute into an invocation-level resource, but production success depends on understanding concurrency, retries, event semantics, downstream limits, and the lifecycle of an ephemeral runtime.

Lambda is a strong fit when work can be expressed as bounded, stateless, independently retryable units. It removes server management, not distributed-systems design. Teams get the most value when functions stay focused, events carry durable intent, idempotency is deliberate, and concurrency is treated as both a scaling mechanism and a safety control.

The practical decision is not whether Lambda is powerful. It is whether its operating model fits the system and the team. It is best suited to event processing, API handlers, automation, file and stream transformations, scheduled tasks, integration glue, bursty services, asynchronous workflows, and domain operations that finish within the execution constraints of the selected Lambda model. It is usually a poor fit for steady compute that is cheaper as a continuously utilized service, software needing persistent host state or privileged kernel access, latency profiles that cannot tolerate runtime initialization variance, and monoliths moved into a function without redesigning state, deployment, or failure behavior. That boundary should be written into the architecture decision so later growth does not turn an intentional choice into accidental lock-in.

Field note 02

Build the right mental model

A Lambda function combines code, configuration, an execution role, and one or more versions or aliases. An invocation runs inside an isolated execution environment. AWS may create new environments as concurrency grows, reuse warm environments for later invocations, freeze them between work, and retire them without notice. Local memory and the temporary file system can accelerate an invocation but are not durable state. Event sources differ: some invoke synchronously, some queue asynchronous events, and poll-based integrations read streams or queues through event-source mappings. Those semantics shape retry, ordering, batching, and error handling.

Memory is the principal performance control and also influences available CPU. Timeout bounds an attempt; reserved concurrency fences a function’s share of regional capacity; provisioned concurrency keeps initialized environments ready for latency-sensitive paths. Versions provide immutable code-and-configuration snapshots, while aliases create stable endpoints and can shift traffic between versions. Layers and container-image packaging address dependency delivery, not state. Destinations, dead-letter patterns, partial batch responses, and event filtering help make asynchronous flows observable and recoverable. Standard functions have a finite invocation duration; current Lambda documentation also distinguishes durable, longer-running orchestration models, so architects must identify which semantics they are actually adopting.

Separate the control plane from the data plane in both design and incident response. The control plane creates configuration and desired state; the data plane carries production work. A deployment API succeeding does not prove that traffic, jobs, or events are healthy. Conversely, a transient control-plane problem should not automatically stop already-running work. Document which APIs are needed during steady state, which are needed only for change, and which dependencies sit on the critical request path.

Make ownership boundaries visible. Identity, network reachability, encryption keys, artifacts, telemetry, quotas, and billing dimensions frequently belong to different teams. A service can be technically managed while the surrounding system remains unmanaged. Name an owner for the application, the platform configuration, the data, the recovery procedure, and the cost model. That simple map prevents the most common failure mode in cloud programs: assuming an abstraction transferred a responsibility that it only moved.

Field note 03

Where it earns its keep

The strongest Lambda architectures begin with a workload whose constraints align with the service. The following patterns are starting points, not product marketing categories. Each still needs an explicit data model, failure model, and ownership model.

Do not choose a cloud service from the deployment demo alone. A demo proves that the happy path exists; an architecture decision must explain day-two change, degraded dependencies, recovery, security evidence, and cost under real load. For Lambda, those questions reveal whether the service removes undifferentiated work or merely postpones it.

  • Event transformation: Objects, messages, and change streams can trigger focused validation, enrichment, routing, and indexing without maintaining a permanent worker fleet.
  • Bursty APIs and automation: Request handlers, scheduled operations, account automation, and webhook processing benefit when demand is irregular and each unit is bounded.
  • Composable workflows: Functions provide isolated domain steps inside event-driven or orchestrated processes when checkpoints and external effects are explicit.
Field note 04

Architecture moves that age well

A useful reference architecture is a set of constraints with reasons, not a diagram crowded with service icons. Start with the moves below, assign an owner to each, and encode the ones that can be enforced. Exceptions should include an expiration date and a test that proves why the normal path does not work.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

  • Design every side-effecting handler for duplicate delivery and safe replay.
  • Use queues to absorb bursts and set consumer concurrency from downstream capacity, not from Lambda’s maximum.
  • Publish immutable versions and promote aliases through staged, observable traffic shifts.
  • Keep durable state in purpose-built services; treat warm memory and temporary disk strictly as caches.
Field note 05

Scaling and performance

Lambda scales through concurrency: more simultaneous work creates more execution environments, subject to regional, per-function, and source-specific behavior. A function can scale faster than a database, vendor API, NAT path, or account quota behind it. Reserved concurrency can protect critical functions or deliberately cap pressure on a dependency. Queue-based consumers need batch size, visibility timeout, maximum concurrency, and failure isolation tuned together. Stream consumers also care about shard parallelization and ordering. Performance work should measure end-to-end latency, initialization, handler duration, throttles, retries, iterator age, and downstream saturation—not just the function’s average duration.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

Performance tuning must preserve correctness. Optimize the slowest meaningful business path, verify the change against a representative distribution, and watch for work displaced into queues, retries, caches, or operators. With Lambda, a lower service-level latency can still create a worse system if downstream saturation, recovery backlog, or cost per completed transaction rises. Keep load-test artifacts and capacity assumptions versioned beside the architecture.

Field note 06

Security and governance

Give each function a narrow execution role and separate deployment permissions from runtime permissions. Store secrets in a managed secret service and cache them carefully within a reusable environment. Validate every event, including events originating from trusted AWS services, because object keys, message bodies, and request fields remain untrusted data. Control network access intentionally: attaching a function to a VPC changes how it reaches private resources and the public internet. Encrypt environment variables where appropriate, sign or govern deployment artifacts, scan dependencies, and keep managed runtimes on supported versions because runtime updates and deprecations are part of the service lifecycle.

Use least privilege as an engineering process, not a one-time IAM document. Begin with separate human, deployment, and runtime identities. Observe required actions, narrow resources and conditions, and add explicit organization guardrails for high-impact operations. Encrypt data in transit and at rest, but also design key ownership, rotation, deletion protection, and break-glass access. Centralize audit records in an account and storage boundary that a compromised workload cannot rewrite.

Threat-model Lambda across four surfaces: the management API, the workload’s runtime identity, the network and event inputs that reach it, and the software or configuration artifact that is deployed. Add the data stores and observability pipeline as separate trust boundaries. Preventive controls reduce the reachable state space; detective controls shorten time to evidence; recovery controls make destructive events survivable. A mature design has all three and tests them independently.

Governance should make the secure path faster. Provide approved modules, narrowly scoped roles, standard encryption and logging defaults, ownership tags, and automated evidence. Block dangerous configurations at the organization or pipeline boundary when the intent is unambiguous. Leave application teams enough room to tune the workload without letting every team invent identity, ingress, logging, and incident access from scratch.

Field note 07

Reliability and recovery

Retries are part of normal Lambda operation, so side effects must be idempotent. Synchronous clients, asynchronous invocation, queues, and streams all have different retry owners and retention windows. Store a durable idempotency key or conditional write before performing non-repeatable work. Use dead-letter or failure destinations for records that exhaust attempts, but treat those destinations as operational queues with alarms and replay tooling. Make timeouts shorter than upstream deadlines and align queue visibility with worst-case attempts. Test duplicate, delayed, reordered, poison, oversized, and partially failed batches. A successful invocation metric does not guarantee the business transaction completed.

Define failure in business terms before selecting a recovery mechanism. Availability, durability, recovery time, and recovery point are different objectives. Multi-zone placement improves some infrastructure failures but does not repair corrupt deployments or deleted data. Backups address some data events but do not guarantee a runnable application. Use layered controls: health-based replacement, redundancy, deployment rollback, data protection, quota monitoring, and a rehearsed regional or organizational recovery path where the business requires one.

Write failure-mode tests for Lambda before the first serious incident. Include unavailable capacity, throttled control APIs, expired credentials, bad configuration, dependency timeout, partial deployment, telemetry loss, and operator error. Test what happens to in-flight work, how the system detects the condition, who is paged, and how replay or rollback avoids duplicate effects. Recovery time measured in a game day is more credible than recovery time copied from a diagram.

Keep the recovery path simpler than the primary path. If restoration depends on the same identity, network, artifact repository, region, or specialist that the incident removed, it is not independent. Store runbooks where responders can reach them, pre-authorize narrowly scoped emergency actions, and verify backups by restoring into an isolated environment. Record the achieved recovery point and time so business owners can compare evidence with policy.

Field note 08

Cost and capacity economics

Lambda charges primarily for requests and duration according to allocated resources, with adjacent costs for logs, data movement, API front doors, queues, streams, orchestration, VPC connectivity, and provisioned capacity. It excels when utilization is intermittent or highly variable because idle execution environments do not become customer-managed servers. For steady, high-volume work, compare the complete architecture with containers or instances at realistic utilization. Optimize code and memory together: more memory can shorten duration enough to improve both latency and cost. Excessive function fragmentation can also create hidden observability and integration spend.

Evaluate unit economics at the level customers consume: cost per request, job, simulation, tenant, build, or environment. Tagging helps allocation, but architecture determines most spend. Include idle baseline, burst premium, storage growth, log retention, data transfer, support, licenses, and operator time. Rate discounts should follow rightsizing and workload-shape work. A commitment applied to the wrong baseline converts an optimization opportunity into a contract.

Create a cost model for Lambda with a low, expected, and stress scenario. Tie every variable to a measurable workload characteristic and identify which team can influence it. Alarm on anomalous unit cost as well as total spend; total spend naturally rises with successful products, while unit cost exposes architectural drift. Review unused capacity and retained artifacts on a schedule, and give every long-lived resource an owner and lifecycle policy.

Optimization should preserve reliability margins. Removing all idle capacity, shortening every retention period, or consolidating every boundary may lower a spreadsheet while increasing incident probability and recovery time. Price the resilience requirement explicitly. Then apply the least risky lever first: eliminate waste, rightsize, improve utilization, reduce unnecessary transfer, select the correct purchasing model, and only then make longer commitments.

Field note 09

Operating it in production

Publish structured logs with correlation identifiers, emit domain metrics, trace cross-service requests selectively, and alarm on errors, throttles, age, dead-letter depth, and downstream health. Use aliases for controlled promotion and roll back by moving an alias, not rebuilding an artifact. Reproduce production event shapes in tests and maintain replay tools that redact sensitive data. Keep function configuration in infrastructure as code. Review quotas and runtime support dates. A mature serverless team operates event contracts and failure queues with the same discipline that an infrastructure team applies to hosts.

Treat configuration as versioned product code. Changes should pass static checks, policy checks, integration tests, and an environment that resembles production. Promote the same artifact; do not rebuild it differently at every stage. Prefer gradual exposure, observable health gates, and automated rollback for reversible changes. For irreversible data or identity changes, use expansion-and-contraction patterns and explicit checkpoints. Record who changed what, why, and which measured signal declared the change safe.

Build one operational view that links Lambda health to customer outcomes. Infrastructure metrics explain resources, application metrics explain behavior, traces explain selected paths, and logs provide detailed evidence. None is sufficient alone. Define symptom-based alerts around availability, latency, backlog, freshness, correctness, and saturation; route them to an accountable team; and attach the first diagnostic action. Remove alerts that never change a decision.

Run a monthly service review until the platform is boring. Examine incidents, near misses, failed changes, quota headroom, runtime or image lifecycle, cost per unit, access exceptions, recovery evidence, and support announcements. Convert repeated manual actions into automation only after the team understands the decision being automated. Good operations reduce surprise without hiding state from the people accountable for it.

Field note 10

Failure patterns to avoid

Most expensive mistakes are reasonable shortcuts that survived beyond their original context. Treat these risks as design-review prompts. Ask which control detects each condition, how quickly the team can recover, and whether the workload can be moved or reshaped before the risk becomes a constraint.

A risk register is useful only when it changes action. Give each item an owner, leading indicator, mitigation, and review date. If a risk is accepted, record the business reason. If it is mitigated, test the mitigation. If it is transferred to a managed service, verify the exact responsibility that moved instead of assuming the service name moved all of it.

  • Unbounded concurrency can transform a traffic spike into a database or vendor outage.
  • Retry behavior differs by event source and is often misunderstood until poison records appear.
  • A function-per-line architecture increases deployment, tracing, and ownership complexity.
  • Runtime deprecations and automatic updates require planned testing rather than passive trust.
Field note 11

Alternatives and the decision

Fargate and App Runner-style services fit longer-lived HTTP or worker processes and provide a familiar container boundary. EC2 fits host-level control and specialized runtime requirements. Step Functions coordinates explicit workflows; Lambda supplies units of work within many of those workflows. Durable Lambda capabilities may reduce some orchestration code, but they do not erase the need to model checkpoints, compensation, and external effects. The decision should compare execution semantics, concurrency shape, latency, and organizational operations—not simply label one option serverless and another traditional.

Adopt Lambda as an event compute platform, not a place to hide arbitrary application code. Establish common libraries for observability and idempotency, approved event patterns, concurrency budgets, deployment aliases, and runtime lifecycle management. Then let teams create small functions where the domain boundary supports them. When a function accumulates persistent connections, long loops, large mutable state, or constant high utilization, move that portion to a service model rather than fighting the invocation model.

Use a short proof of architecture when uncertainty is material. Test the hardest requirement, the most important failure mode, and the expected cost driver—not another hello-world deployment. Compare Lambda with the strongest alternative using the same workload and evidence. Record the decision, rejected options, assumptions, migration trigger, and date for review. Architecture remains healthy when a future team can understand both why the choice was correct and which changed fact would make it wrong.

Field note 12

A pragmatic 90-day adoption plan

Days 1–15: define the workload and responsibility map. Capture traffic or job shape, data sensitivity, availability and recovery objectives, latency, unit economics, dependencies, regional constraints, and team ownership. Build a thin threat model and request quota changes early. Select one representative path for the proof, not the easiest path. Establish a clean account, identity, network, artifact, encryption, and logging baseline before application convenience creates permanent exceptions.

Days 16–35: implement a production-shaped walking skeleton on Lambda. Provision it from code, deploy an immutable artifact, integrate one real dependency, emit structured telemetry, and prove that a new team member can reproduce the environment. Exercise duplicate work, bad input, dependency timeout, and lost capacity. Measure cold and warm behavior where relevant, saturation, recovery backlog, and cost per successful business unit.

Days 36–60: harden delivery and recovery. Add policy checks, staged promotion, rollback or replacement, least-privilege runtime identity, secret rotation, data protection, retention, and symptom-based alerts. Restore from backup or recreate from artifacts in an isolated environment. Run a game day that includes an operator mistake and a compromised credential. Convert the findings into platform defaults and owned backlog items rather than a slide deck.

Days 61–90: place controlled production load on the service, review evidence with security, finance, and operations, and compare observed behavior with the original decision. Publish a paved-road module, dashboard, runbook, and exception process. Set capacity and cost review thresholds. Finally, write the exit criteria: the scale, feature, compliance need, economics, or organizational change that would trigger a move away from Lambda. A reversible decision is easier to make well.
Posted in Compute | Tagged: , , , , , , , , , , , | Leave a Comment »

AWS Lake Formation Deep Dive: Architecture, Security, Cost & Operations

Posted by Sriram Sanka on August 18, 2026

AWS Lake Formation architecture diagram
AWS Lake Formation architecture and operating-boundary overview.

AWS Lake Formation provides governed data-lake permissions, sharing, catalogs, and administrative workflows. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Governed data-lake permissions, sharing, catalogs, and administrative workflows
Primary operating unit: record, event, query, job, table, stream, dashboard, or data product
Decision boundary: freshness, schema, governance, compute isolation, quality, and unit economics
Field note 01

The short version

AWS Lake Formation provides governed data-lake permissions, sharing, catalogs, and administrative workflows. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Adopt AWS Lake Formation when governed data-lake permissions, sharing, catalogs, and administrative workflows is an enduring workload requirement and the managed boundary removes work your organization does not need to differentiate. The service decision should be based on measurable behavior and ownership, not catalog breadth. A proof must exercise the hardest integration, the most credible failure, the security boundary, and the dominant unit-cost driver before the design is standardized.

The practical decision is not whether AWS Lake Formation is powerful. It is whether its operating model fits the system and the team. It is best suited to workloads that explicitly need governed data-lake permissions, sharing, catalogs, and administrative workflows; teams prepared to operate the surrounding identity, network, data, telemetry, delivery, and recovery controls; and platforms that can measure each record, event, query, job, table, stream, dashboard, or data product. It is usually a poor fit for systems whose requirement can be met by a different analytical engine, operational database, or external data platform; teams without an accountable service owner; or designs that cannot explain freshness, schema, governance, compute isolation, quality, and unit economics before production traffic arrives. That boundary should be written into the architecture decision so later growth does not turn an intentional choice into accidental lock-in.

Field note 02

Build the right mental model

Think of AWS Lake Formation as a managed control plane around each record, event, query, job, table, stream, dashboard, or data product. The service accepts desired state, policy, configuration, or workload input, then coordinates AWS-owned infrastructure to deliver governed data-lake permissions, sharing, catalogs, and administrative workflows. The exact managed boundary varies by feature and region, but the architectural pattern is stable: management APIs change configuration, resource policies and IAM decide who may act, service endpoints carry production work, telemetry reports selected behavior, and quotas bound how quickly the system can grow. Customer data, application correctness, access choices, downstream dependencies, and business recovery remain customer concerns even when infrastructure replacement is automated.

A production implementation begins with account and region placement, least-privilege administrative and runtime roles, network reachability, encryption ownership, quotas, logging, tags, and configuration expressed as code. For AWS Lake Formation, define the authoritative resource model, immutable or versioned deployment unit, and the path from a reviewed change to active service behavior. Identify asynchronous operations, eventual consistency, retry semantics, deletion behavior, and every resource created indirectly. Record which actions are safe to repeat, which require a change window, and which can cause data loss or customer-visible interruption.

Separate the control plane from the data plane in both design and incident response. The control plane creates configuration and desired state; the data plane carries production work. A deployment API succeeding does not prove that traffic, jobs, or events are healthy. Conversely, a transient control-plane problem should not automatically stop already-running work. Document which APIs are needed during steady state, which are needed only for change, and which dependencies sit on the critical request path.

Make ownership boundaries visible. Identity, network reachability, encryption keys, artifacts, telemetry, quotas, and billing dimensions frequently belong to different teams. A service can be technically managed while the surrounding system remains unmanaged. Name an owner for the application, the platform configuration, the data, the recovery procedure, and the cost model. That simple map prevents the most common failure mode in cloud programs: assuming an abstraction transferred a responsibility that it only moved.

Field note 03

Where it earns its keep

The strongest AWS Lake Formation architectures begin with a workload whose constraints align with the service. The following patterns are starting points, not product marketing categories. Each still needs an explicit data model, failure model, and ownership model.

Do not choose a cloud service from the deployment demo alone. A demo proves that the happy path exists; an architecture decision must explain day-two change, degraded dependencies, recovery, security evidence, and cost under real load. For AWS Lake Formation, those questions reveal whether the service removes undifferentiated work or merely postpones it.

  • Primary production pattern: Use AWS Lake Formation where governed data-lake permissions, sharing, catalogs, and administrative workflows is on the critical path and the team can own the surrounding controls.
  • Governed shared capability: A platform team can package identity, policy, telemetry, cost allocation, and recovery defaults for multiple consumers.
  • Migration or modernization: Adopt the managed boundary incrementally while preserving data validation, rollback, and an explicit exit path.
Field note 04

Architecture moves that age well

A useful reference architecture is a set of constraints with reasons, not a diagram crowded with service icons. Start with the moves below, assign an owner to each, and encode the ones that can be enforced. Exceptions should include an expiration date and a test that proves why the normal path does not work.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

  • Define the authoritative AWS Lake Formation resource model and provision it from reviewed, versioned configuration.
  • Measure capacity, latency, failure, and cost per record, event, query, job, table, stream, dashboard, or data product under production-shaped load.
  • Separate administrative, deployment, and runtime identities and centralize evidence outside the workload boundary.
  • Test restoration or replacement and document the requirement that would trigger an exit from AWS Lake Formation.
Field note 05

Scaling and performance

AWS Lake Formation capacity should be planned from the arrival rate and shape of each record, event, query, job, table, stream, dashboard, or data product, not from an average utilization graph. Model steady load, bursts, backlog, object or payload size, concurrency, retention, dependency ceilings, and regional quotas. Separate a control-plane request being accepted from capacity becoming usable. Measure provisioning, warm-up, propagation, and recovery time. Where scaling is automatic, set guardrails that protect downstream systems and budgets. Where it is manual, define leading indicators and enough headroom for failure plus deployment overlap.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

Performance tuning must preserve correctness. Optimize the slowest meaningful business path, verify the change against a representative distribution, and watch for work displaced into queues, retries, caches, or operators. With AWS Lake Formation, a lower service-level latency can still create a worse system if downstream saturation, recovery backlog, or cost per completed transaction rises. Keep load-test artifacts and capacity assumptions versioned beside the architecture.

Field note 06

Security and governance

Secure AWS Lake Formation through explicit trust boundaries. Separate human administration, deployment automation, and runtime access; narrow actions and resources; use short-lived credentials; and apply organization guardrails to public exposure, deletion, cross-account sharing, and encryption changes. Protect data in transit and at rest with a documented key model. Send audit and security evidence to a boundary the workload cannot rewrite. Validate untrusted names, payloads, metadata, and configuration even when they arrive through an AWS integration. Treat service-linked roles, resource policies, grants, endpoints, and delegated administration as production code.

Use least privilege as an engineering process, not a one-time IAM document. Begin with separate human, deployment, and runtime identities. Observe required actions, narrow resources and conditions, and add explicit organization guardrails for high-impact operations. Encrypt data in transit and at rest, but also design key ownership, rotation, deletion protection, and break-glass access. Centralize audit records in an account and storage boundary that a compromised workload cannot rewrite.

Threat-model AWS Lake Formation across four surfaces: the management API, the workload’s runtime identity, the network and event inputs that reach it, and the software or configuration artifact that is deployed. Add the data stores and observability pipeline as separate trust boundaries. Preventive controls reduce the reachable state space; detective controls shorten time to evidence; recovery controls make destructive events survivable. A mature design has all three and tests them independently.

Governance should make the secure path faster. Provide approved modules, narrowly scoped roles, standard encryption and logging defaults, ownership tags, and automated evidence. Block dangerous configurations at the organization or pipeline boundary when the intent is unambiguous. Leave application teams enough room to tune the workload without letting every team invent identity, ingress, logging, and incident access from scratch.

Field note 07

Reliability and recovery

Reliability for AWS Lake Formation is the ability to preserve the intended business outcome when a zone, region, dependency, credential, quota, configuration, or operator action fails. Determine which components are regional or zonal and which state is durable, replicated, restorable, or reproducible. Set recovery-time and recovery-point objectives, then build the smallest mechanism that meets them. Test throttling, unavailable capacity, partial completion, duplicate delivery, stale configuration, corrupted input, telemetry loss, and recovery into an isolated environment. A multi-AZ service does not make a single-region or single-account application automatically recoverable.

Define failure in business terms before selecting a recovery mechanism. Availability, durability, recovery time, and recovery point are different objectives. Multi-zone placement improves some infrastructure failures but does not repair corrupt deployments or deleted data. Backups address some data events but do not guarantee a runnable application. Use layered controls: health-based replacement, redundancy, deployment rollback, data protection, quota monitoring, and a rehearsed regional or organizational recovery path where the business requires one.

Write failure-mode tests for AWS Lake Formation before the first serious incident. Include unavailable capacity, throttled control APIs, expired credentials, bad configuration, dependency timeout, partial deployment, telemetry loss, and operator error. Test what happens to in-flight work, how the system detects the condition, who is paged, and how replay or rollback avoids duplicate effects. Recovery time measured in a game day is more credible than recovery time copied from a diagram.

Keep the recovery path simpler than the primary path. If restoration depends on the same identity, network, artifact repository, region, or specialist that the incident removed, it is not independent. Store runbooks where responders can reach them, pre-authorize narrowly scoped emergency actions, and verify backups by restoring into an isolated environment. Record the achieved recovery point and time so business owners can compare evidence with policy.

Field note 08

Cost and capacity economics

Model AWS Lake Formation with a unit that finance and engineering both understand: cost per record, event, query, job, table, stream, dashboard, or data product. Include baseline resources, request or execution charges, storage and retention, logs, network transfer, cross-zone or cross-region movement, encryption and security services, backups, support, licenses, and operator time. Build expected and stress scenarios, attach owners to long-lived resources, and alarm on abnormal unit cost. Remove waste and rightsize before purchasing commitments. Preserve the capacity and retention margins required by the reliability objective instead of treating every idle byte or spare unit as waste.

Evaluate unit economics at the level customers consume: cost per request, job, simulation, tenant, build, or environment. Tagging helps allocation, but architecture determines most spend. Include idle baseline, burst premium, storage growth, log retention, data transfer, support, licenses, and operator time. Rate discounts should follow rightsizing and workload-shape work. A commitment applied to the wrong baseline converts an optimization opportunity into a contract.

Create a cost model for AWS Lake Formation with a low, expected, and stress scenario. Tie every variable to a measurable workload characteristic and identify which team can influence it. Alarm on anomalous unit cost as well as total spend; total spend naturally rises with successful products, while unit cost exposes architectural drift. Review unused capacity and retained artifacts on a schedule, and give every long-lived resource an owner and lifecycle policy.

Optimization should preserve reliability margins. Removing all idle capacity, shortening every retention period, or consolidating every boundary may lower a spreadsheet while increasing incident probability and recovery time. Price the resilience requirement explicitly. Then apply the least risky lever first: eliminate waste, rightsize, improve utilization, reduce unnecessary transfer, select the correct purchasing model, and only then make longer commitments.

Field note 09

Operating it in production

Operate AWS Lake Formation as a product with a named owner, versioned modules, approved defaults, dashboards, runbooks, lifecycle reviews, and an exception process. Monitor customer symptoms and service saturation together. Track change success, quota headroom, access exceptions, failed operations, recovery evidence, spend, and AWS lifecycle announcements. Provide developers a paved contract that hides repetitive configuration without hiding state. Review incidents and near misses monthly until routine replacement, rollback, replay, access recertification, and recovery are boring and evidenced.

Treat configuration as versioned product code. Changes should pass static checks, policy checks, integration tests, and an environment that resembles production. Promote the same artifact; do not rebuild it differently at every stage. Prefer gradual exposure, observable health gates, and automated rollback for reversible changes. For irreversible data or identity changes, use expansion-and-contraction patterns and explicit checkpoints. Record who changed what, why, and which measured signal declared the change safe.

Build one operational view that links AWS Lake Formation health to customer outcomes. Infrastructure metrics explain resources, application metrics explain behavior, traces explain selected paths, and logs provide detailed evidence. None is sufficient alone. Define symptom-based alerts around availability, latency, backlog, freshness, correctness, and saturation; route them to an accountable team; and attach the first diagnostic action. Remove alerts that never change a decision.

Run a monthly service review until the platform is boring. Examine incidents, near misses, failed changes, quota headroom, runtime or image lifecycle, cost per unit, access exceptions, recovery evidence, and support announcements. Convert repeated manual actions into automation only after the team understands the decision being automated. Good operations reduce surprise without hiding state from the people accountable for it.

Field note 10

Failure patterns to avoid

Most expensive mistakes are reasonable shortcuts that survived beyond their original context. Treat these risks as design-review prompts. Ask which control detects each condition, how quickly the team can recover, and whether the workload can be moved or reshaped before the risk becomes a constraint.

A risk register is useful only when it changes action. Give each item an owner, leading indicator, mitigation, and review date. If a risk is accepted, record the business reason. If it is mitigated, test the mitigation. If it is transferred to a managed service, verify the exact responsibility that moved instead of assuming the service name moved all of it.

  • The team assumes AWS Lake Formation transfers application, data, or recovery responsibility that remains with the customer.
  • Automatic scale reaches a quota or overwhelms a downstream dependency before alerts explain the symptom.
  • Manual console changes create drift from the reviewed configuration and weaken incident reconstruction.
  • A lifecycle, pricing, regional, or feature change is discovered only after the architecture depends on it.
Field note 11

Alternatives and the decision

Compare AWS Lake Formation with a different analytical engine, operational database, or external data platform using the same workload, security assumptions, recovery target, and cost horizon. A managed service can reduce infrastructure labor while increasing product-specific policy, integration, and exit work. Portability of data formats or APIs does not guarantee portability of identity, monitoring, automation, or operating knowledge. The strongest decision states what AWS Lake Formation uniquely contributes, what the organization still owns, and which changed requirement would trigger a different platform.

AWS Lake Formation is a sound choice when the requirement for governed data-lake permissions, sharing, catalogs, and administrative workflows is concrete, the managed boundary is understood, and the team can operate the complete system around it. Start with a production-shaped proof, constrain variation, automate safe defaults, and retain an exit path through portable data, documented configuration, and reproducible artifacts. If the service is marked preview, changing, renamed, or retired, treat availability and lifecycle constraints as first-class architecture inputs rather than documentation footnotes.

Use a short proof of architecture when uncertainty is material. Test the hardest requirement, the most important failure mode, and the expected cost driver—not another hello-world deployment. Compare AWS Lake Formation with the strongest alternative using the same workload and evidence. Record the decision, rejected options, assumptions, migration trigger, and date for review. Architecture remains healthy when a future team can understand both why the choice was correct and which changed fact would make it wrong.

Field note 12

A pragmatic 90-day adoption plan

Days 1–15: define the workload and responsibility map. Capture traffic or job shape, data sensitivity, availability and recovery objectives, latency, unit economics, dependencies, regional constraints, and team ownership. Build a thin threat model and request quota changes early. Select one representative path for the proof, not the easiest path. Establish a clean account, identity, network, artifact, encryption, and logging baseline before application convenience creates permanent exceptions.

Days 16–35: implement a production-shaped walking skeleton on AWS Lake Formation. Provision it from code, deploy an immutable artifact, integrate one real dependency, emit structured telemetry, and prove that a new team member can reproduce the environment. Exercise duplicate work, bad input, dependency timeout, and lost capacity. Measure cold and warm behavior where relevant, saturation, recovery backlog, and cost per successful business unit.

Days 36–60: harden delivery and recovery. Add policy checks, staged promotion, rollback or replacement, least-privilege runtime identity, secret rotation, data protection, retention, and symptom-based alerts. Restore from backup or recreate from artifacts in an isolated environment. Run a game day that includes an operator mistake and a compromised credential. Convert the findings into platform defaults and owned backlog items rather than a slide deck.

Days 61–90: place controlled production load on the service, review evidence with security, finance, and operations, and compare observed behavior with the original decision. Publish a paved-road module, dashboard, runbook, and exception process. Set capacity and cost review thresholds. Finally, write the exit criteria: the scale, feature, compliance need, economics, or organizational change that would trigger a move away from AWS Lake Formation. A reversible decision is easier to make well.

Posted in Analytics | Tagged: , , , , , , , , , , , | Leave a Comment »

AWS Key Management Service Deep Dive: Architecture, Security, Cost & Operations

Posted by Sriram Sanka on August 18, 2026

AWS Key Management Service architecture diagram
AWS Key Management Service architecture and operating-boundary overview.

AWS Key Management Service provides managed encryption keys, policies, grants, cryptographic operations, and audit. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Managed encryption keys, policies, grants, cryptographic operations, and audit
Primary operating unit: principal, policy decision, secret, key, certificate, finding, or evidence item
Decision boundary: trust, authorization, cryptographic ownership, detection, response, and auditability
Field note 01

The short version

AWS Key Management Service provides managed encryption keys, policies, grants, cryptographic operations, and audit. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Adopt AWS Key Management Service when managed encryption keys, policies, grants, cryptographic operations, and audit is an enduring workload requirement and the managed boundary removes work your organization does not need to differentiate. The service decision should be based on measurable behavior and ownership, not catalog breadth. A proof must exercise the hardest integration, the most credible failure, the security boundary, and the dominant unit-cost driver before the design is standardized.

The practical decision is not whether AWS Key Management Service is powerful. It is whether its operating model fits the system and the team. It is best suited to workloads that explicitly need managed encryption keys, policies, grants, cryptographic operations, and audit; teams prepared to operate the surrounding identity, network, data, telemetry, delivery, and recovery controls; and platforms that can measure each principal, policy decision, secret, key, certificate, finding, or evidence item. It is usually a poor fit for systems whose requirement can be met by another native security control, an external platform, or a simpler identity boundary; teams without an accountable service owner; or designs that cannot explain trust, authorization, cryptographic ownership, detection, response, and auditability before production traffic arrives. That boundary should be written into the architecture decision so later growth does not turn an intentional choice into accidental lock-in.

Field note 02

Build the right mental model

Think of AWS Key Management Service as a managed control plane around each principal, policy decision, secret, key, certificate, finding, or evidence item. The service accepts desired state, policy, configuration, or workload input, then coordinates AWS-owned infrastructure to deliver managed encryption keys, policies, grants, cryptographic operations, and audit. The exact managed boundary varies by feature and region, but the architectural pattern is stable: management APIs change configuration, resource policies and IAM decide who may act, service endpoints carry production work, telemetry reports selected behavior, and quotas bound how quickly the system can grow. Customer data, application correctness, access choices, downstream dependencies, and business recovery remain customer concerns even when infrastructure replacement is automated.

A production implementation begins with account and region placement, least-privilege administrative and runtime roles, network reachability, encryption ownership, quotas, logging, tags, and configuration expressed as code. For AWS Key Management Service, define the authoritative resource model, immutable or versioned deployment unit, and the path from a reviewed change to active service behavior. Identify asynchronous operations, eventual consistency, retry semantics, deletion behavior, and every resource created indirectly. Record which actions are safe to repeat, which require a change window, and which can cause data loss or customer-visible interruption.

Separate the control plane from the data plane in both design and incident response. The control plane creates configuration and desired state; the data plane carries production work. A deployment API succeeding does not prove that traffic, jobs, or events are healthy. Conversely, a transient control-plane problem should not automatically stop already-running work. Document which APIs are needed during steady state, which are needed only for change, and which dependencies sit on the critical request path.

Make ownership boundaries visible. Identity, network reachability, encryption keys, artifacts, telemetry, quotas, and billing dimensions frequently belong to different teams. A service can be technically managed while the surrounding system remains unmanaged. Name an owner for the application, the platform configuration, the data, the recovery procedure, and the cost model. That simple map prevents the most common failure mode in cloud programs: assuming an abstraction transferred a responsibility that it only moved.

Field note 03

Where it earns its keep

The strongest AWS Key Management Service architectures begin with a workload whose constraints align with the service. The following patterns are starting points, not product marketing categories. Each still needs an explicit data model, failure model, and ownership model.

Do not choose a cloud service from the deployment demo alone. A demo proves that the happy path exists; an architecture decision must explain day-two change, degraded dependencies, recovery, security evidence, and cost under real load. For AWS Key Management Service, those questions reveal whether the service removes undifferentiated work or merely postpones it.

  • Primary production pattern: Use AWS Key Management Service where managed encryption keys, policies, grants, cryptographic operations, and audit is on the critical path and the team can own the surrounding controls.
  • Governed shared capability: A platform team can package identity, policy, telemetry, cost allocation, and recovery defaults for multiple consumers.
  • Migration or modernization: Adopt the managed boundary incrementally while preserving data validation, rollback, and an explicit exit path.
Field note 04

Architecture moves that age well

A useful reference architecture is a set of constraints with reasons, not a diagram crowded with service icons. Start with the moves below, assign an owner to each, and encode the ones that can be enforced. Exceptions should include an expiration date and a test that proves why the normal path does not work.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

  • Define the authoritative AWS Key Management Service resource model and provision it from reviewed, versioned configuration.
  • Measure capacity, latency, failure, and cost per principal, policy decision, secret, key, certificate, finding, or evidence item under production-shaped load.
  • Separate administrative, deployment, and runtime identities and centralize evidence outside the workload boundary.
  • Test restoration or replacement and document the requirement that would trigger an exit from AWS Key Management Service.
Field note 05

Scaling and performance

AWS Key Management Service capacity should be planned from the arrival rate and shape of each principal, policy decision, secret, key, certificate, finding, or evidence item, not from an average utilization graph. Model steady load, bursts, backlog, object or payload size, concurrency, retention, dependency ceilings, and regional quotas. Separate a control-plane request being accepted from capacity becoming usable. Measure provisioning, warm-up, propagation, and recovery time. Where scaling is automatic, set guardrails that protect downstream systems and budgets. Where it is manual, define leading indicators and enough headroom for failure plus deployment overlap.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

Performance tuning must preserve correctness. Optimize the slowest meaningful business path, verify the change against a representative distribution, and watch for work displaced into queues, retries, caches, or operators. With AWS Key Management Service, a lower service-level latency can still create a worse system if downstream saturation, recovery backlog, or cost per completed transaction rises. Keep load-test artifacts and capacity assumptions versioned beside the architecture.

Field note 06

Security and governance

Secure AWS Key Management Service through explicit trust boundaries. Separate human administration, deployment automation, and runtime access; narrow actions and resources; use short-lived credentials; and apply organization guardrails to public exposure, deletion, cross-account sharing, and encryption changes. Protect data in transit and at rest with a documented key model. Send audit and security evidence to a boundary the workload cannot rewrite. Validate untrusted names, payloads, metadata, and configuration even when they arrive through an AWS integration. Treat service-linked roles, resource policies, grants, endpoints, and delegated administration as production code.

Use least privilege as an engineering process, not a one-time IAM document. Begin with separate human, deployment, and runtime identities. Observe required actions, narrow resources and conditions, and add explicit organization guardrails for high-impact operations. Encrypt data in transit and at rest, but also design key ownership, rotation, deletion protection, and break-glass access. Centralize audit records in an account and storage boundary that a compromised workload cannot rewrite.

Threat-model AWS Key Management Service across four surfaces: the management API, the workload’s runtime identity, the network and event inputs that reach it, and the software or configuration artifact that is deployed. Add the data stores and observability pipeline as separate trust boundaries. Preventive controls reduce the reachable state space; detective controls shorten time to evidence; recovery controls make destructive events survivable. A mature design has all three and tests them independently.

Governance should make the secure path faster. Provide approved modules, narrowly scoped roles, standard encryption and logging defaults, ownership tags, and automated evidence. Block dangerous configurations at the organization or pipeline boundary when the intent is unambiguous. Leave application teams enough room to tune the workload without letting every team invent identity, ingress, logging, and incident access from scratch.

Field note 07

Reliability and recovery

Reliability for AWS Key Management Service is the ability to preserve the intended business outcome when a zone, region, dependency, credential, quota, configuration, or operator action fails. Determine which components are regional or zonal and which state is durable, replicated, restorable, or reproducible. Set recovery-time and recovery-point objectives, then build the smallest mechanism that meets them. Test throttling, unavailable capacity, partial completion, duplicate delivery, stale configuration, corrupted input, telemetry loss, and recovery into an isolated environment. A multi-AZ service does not make a single-region or single-account application automatically recoverable.

Define failure in business terms before selecting a recovery mechanism. Availability, durability, recovery time, and recovery point are different objectives. Multi-zone placement improves some infrastructure failures but does not repair corrupt deployments or deleted data. Backups address some data events but do not guarantee a runnable application. Use layered controls: health-based replacement, redundancy, deployment rollback, data protection, quota monitoring, and a rehearsed regional or organizational recovery path where the business requires one.

Write failure-mode tests for AWS Key Management Service before the first serious incident. Include unavailable capacity, throttled control APIs, expired credentials, bad configuration, dependency timeout, partial deployment, telemetry loss, and operator error. Test what happens to in-flight work, how the system detects the condition, who is paged, and how replay or rollback avoids duplicate effects. Recovery time measured in a game day is more credible than recovery time copied from a diagram.

Keep the recovery path simpler than the primary path. If restoration depends on the same identity, network, artifact repository, region, or specialist that the incident removed, it is not independent. Store runbooks where responders can reach them, pre-authorize narrowly scoped emergency actions, and verify backups by restoring into an isolated environment. Record the achieved recovery point and time so business owners can compare evidence with policy.

Field note 08

Cost and capacity economics

Model AWS Key Management Service with a unit that finance and engineering both understand: cost per principal, policy decision, secret, key, certificate, finding, or evidence item. Include baseline resources, request or execution charges, storage and retention, logs, network transfer, cross-zone or cross-region movement, encryption and security services, backups, support, licenses, and operator time. Build expected and stress scenarios, attach owners to long-lived resources, and alarm on abnormal unit cost. Remove waste and rightsize before purchasing commitments. Preserve the capacity and retention margins required by the reliability objective instead of treating every idle byte or spare unit as waste.

Evaluate unit economics at the level customers consume: cost per request, job, simulation, tenant, build, or environment. Tagging helps allocation, but architecture determines most spend. Include idle baseline, burst premium, storage growth, log retention, data transfer, support, licenses, and operator time. Rate discounts should follow rightsizing and workload-shape work. A commitment applied to the wrong baseline converts an optimization opportunity into a contract.

Create a cost model for AWS Key Management Service with a low, expected, and stress scenario. Tie every variable to a measurable workload characteristic and identify which team can influence it. Alarm on anomalous unit cost as well as total spend; total spend naturally rises with successful products, while unit cost exposes architectural drift. Review unused capacity and retained artifacts on a schedule, and give every long-lived resource an owner and lifecycle policy.

Optimization should preserve reliability margins. Removing all idle capacity, shortening every retention period, or consolidating every boundary may lower a spreadsheet while increasing incident probability and recovery time. Price the resilience requirement explicitly. Then apply the least risky lever first: eliminate waste, rightsize, improve utilization, reduce unnecessary transfer, select the correct purchasing model, and only then make longer commitments.

Field note 09

Operating it in production

Operate AWS Key Management Service as a product with a named owner, versioned modules, approved defaults, dashboards, runbooks, lifecycle reviews, and an exception process. Monitor customer symptoms and service saturation together. Track change success, quota headroom, access exceptions, failed operations, recovery evidence, spend, and AWS lifecycle announcements. Provide developers a paved contract that hides repetitive configuration without hiding state. Review incidents and near misses monthly until routine replacement, rollback, replay, access recertification, and recovery are boring and evidenced.

Treat configuration as versioned product code. Changes should pass static checks, policy checks, integration tests, and an environment that resembles production. Promote the same artifact; do not rebuild it differently at every stage. Prefer gradual exposure, observable health gates, and automated rollback for reversible changes. For irreversible data or identity changes, use expansion-and-contraction patterns and explicit checkpoints. Record who changed what, why, and which measured signal declared the change safe.

Build one operational view that links AWS Key Management Service health to customer outcomes. Infrastructure metrics explain resources, application metrics explain behavior, traces explain selected paths, and logs provide detailed evidence. None is sufficient alone. Define symptom-based alerts around availability, latency, backlog, freshness, correctness, and saturation; route them to an accountable team; and attach the first diagnostic action. Remove alerts that never change a decision.

Run a monthly service review until the platform is boring. Examine incidents, near misses, failed changes, quota headroom, runtime or image lifecycle, cost per unit, access exceptions, recovery evidence, and support announcements. Convert repeated manual actions into automation only after the team understands the decision being automated. Good operations reduce surprise without hiding state from the people accountable for it.

Field note 10

Failure patterns to avoid

Most expensive mistakes are reasonable shortcuts that survived beyond their original context. Treat these risks as design-review prompts. Ask which control detects each condition, how quickly the team can recover, and whether the workload can be moved or reshaped before the risk becomes a constraint.

A risk register is useful only when it changes action. Give each item an owner, leading indicator, mitigation, and review date. If a risk is accepted, record the business reason. If it is mitigated, test the mitigation. If it is transferred to a managed service, verify the exact responsibility that moved instead of assuming the service name moved all of it.

  • The team assumes AWS Key Management Service transfers application, data, or recovery responsibility that remains with the customer.
  • Automatic scale reaches a quota or overwhelms a downstream dependency before alerts explain the symptom.
  • Manual console changes create drift from the reviewed configuration and weaken incident reconstruction.
  • A lifecycle, pricing, regional, or feature change is discovered only after the architecture depends on it.
Field note 11

Alternatives and the decision

Compare AWS Key Management Service with another native security control, an external platform, or a simpler identity boundary using the same workload, security assumptions, recovery target, and cost horizon. A managed service can reduce infrastructure labor while increasing product-specific policy, integration, and exit work. Portability of data formats or APIs does not guarantee portability of identity, monitoring, automation, or operating knowledge. The strongest decision states what AWS Key Management Service uniquely contributes, what the organization still owns, and which changed requirement would trigger a different platform.

AWS Key Management Service is a sound choice when the requirement for managed encryption keys, policies, grants, cryptographic operations, and audit is concrete, the managed boundary is understood, and the team can operate the complete system around it. Start with a production-shaped proof, constrain variation, automate safe defaults, and retain an exit path through portable data, documented configuration, and reproducible artifacts. If the service is marked preview, changing, renamed, or retired, treat availability and lifecycle constraints as first-class architecture inputs rather than documentation footnotes.

Use a short proof of architecture when uncertainty is material. Test the hardest requirement, the most important failure mode, and the expected cost driver—not another hello-world deployment. Compare AWS Key Management Service with the strongest alternative using the same workload and evidence. Record the decision, rejected options, assumptions, migration trigger, and date for review. Architecture remains healthy when a future team can understand both why the choice was correct and which changed fact would make it wrong.

Field note 12

A pragmatic 90-day adoption plan

Days 1–15: define the workload and responsibility map. Capture traffic or job shape, data sensitivity, availability and recovery objectives, latency, unit economics, dependencies, regional constraints, and team ownership. Build a thin threat model and request quota changes early. Select one representative path for the proof, not the easiest path. Establish a clean account, identity, network, artifact, encryption, and logging baseline before application convenience creates permanent exceptions.

Days 16–35: implement a production-shaped walking skeleton on AWS Key Management Service. Provision it from code, deploy an immutable artifact, integrate one real dependency, emit structured telemetry, and prove that a new team member can reproduce the environment. Exercise duplicate work, bad input, dependency timeout, and lost capacity. Measure cold and warm behavior where relevant, saturation, recovery backlog, and cost per successful business unit.

Days 36–60: harden delivery and recovery. Add policy checks, staged promotion, rollback or replacement, least-privilege runtime identity, secret rotation, data protection, retention, and symptom-based alerts. Restore from backup or recreate from artifacts in an isolated environment. Run a game day that includes an operator mistake and a compromised credential. Convert the findings into platform defaults and owned backlog items rather than a slide deck.

Days 61–90: place controlled production load on the service, review evidence with security, finance, and operations, and compare observed behavior with the original decision. Publish a paved-road module, dashboard, runbook, and exception process. Set capacity and cost review thresholds. Finally, write the exit criteria: the scale, feature, compliance need, economics, or organizational change that would trigger a move away from AWS Key Management Service. A reversible decision is easier to make well.

Posted in Security, Identity, & Compliance | Tagged: , , , , , , , , , , , , | Leave a Comment »

AWS IQ Deep Dive: Architecture, Security, Cost & Operations

Posted by Sriram Sanka on August 18, 2026

AWS IQ architecture diagram
AWS IQ architecture and operating-boundary overview.

AWS IQ provides finding and engaging AWS-certified experts for scoped cloud projects. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Finding and engaging AWS-certified experts for scoped cloud projects
Primary operating unit: engagement, case, recommendation, account, or knowledge contribution
Decision boundary: commercial scope, response expectations, shared responsibility, and organizational follow-through
Field note 01

The short version

AWS IQ provides finding and engaging AWS-certified experts for scoped cloud projects. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Adopt AWS IQ when finding and engaging AWS-certified experts for scoped cloud projects is an enduring workload requirement and the managed boundary removes work your organization does not need to differentiate. The service decision should be based on measurable behavior and ownership, not catalog breadth. A proof must exercise the hardest integration, the most credible failure, the security boundary, and the dominant unit-cost driver before the design is standardized.

The practical decision is not whether AWS IQ is powerful. It is whether its operating model fits the system and the team. It is best suited to workloads that explicitly need finding and engaging AWS-certified experts for scoped cloud projects; teams prepared to operate the surrounding identity, network, data, telemetry, delivery, and recovery controls; and platforms that can measure each engagement, case, recommendation, account, or knowledge contribution. It is usually a poor fit for systems whose requirement can be met by internal capability, an AWS partner, or a different support plan; teams without an accountable service owner; or designs that cannot explain commercial scope, response expectations, shared responsibility, and organizational follow-through before production traffic arrives. That boundary should be written into the architecture decision so later growth does not turn an intentional choice into accidental lock-in.

Field note 02

Build the right mental model

Think of AWS IQ as a managed control plane around each engagement, case, recommendation, account, or knowledge contribution. The service accepts desired state, policy, configuration, or workload input, then coordinates AWS-owned infrastructure to deliver finding and engaging AWS-certified experts for scoped cloud projects. The exact managed boundary varies by feature and region, but the architectural pattern is stable: management APIs change configuration, resource policies and IAM decide who may act, service endpoints carry production work, telemetry reports selected behavior, and quotas bound how quickly the system can grow. Customer data, application correctness, access choices, downstream dependencies, and business recovery remain customer concerns even when infrastructure replacement is automated.

A production implementation begins with account and region placement, least-privilege administrative and runtime roles, network reachability, encryption ownership, quotas, logging, tags, and configuration expressed as code. For AWS IQ, define the authoritative resource model, immutable or versioned deployment unit, and the path from a reviewed change to active service behavior. Identify asynchronous operations, eventual consistency, retry semantics, deletion behavior, and every resource created indirectly. Record which actions are safe to repeat, which require a change window, and which can cause data loss or customer-visible interruption.

Separate the control plane from the data plane in both design and incident response. The control plane creates configuration and desired state; the data plane carries production work. A deployment API succeeding does not prove that traffic, jobs, or events are healthy. Conversely, a transient control-plane problem should not automatically stop already-running work. Document which APIs are needed during steady state, which are needed only for change, and which dependencies sit on the critical request path.

Make ownership boundaries visible. Identity, network reachability, encryption keys, artifacts, telemetry, quotas, and billing dimensions frequently belong to different teams. A service can be technically managed while the surrounding system remains unmanaged. Name an owner for the application, the platform configuration, the data, the recovery procedure, and the cost model. That simple map prevents the most common failure mode in cloud programs: assuming an abstraction transferred a responsibility that it only moved.

Field note 03

Where it earns its keep

The strongest AWS IQ architectures begin with a workload whose constraints align with the service. The following patterns are starting points, not product marketing categories. Each still needs an explicit data model, failure model, and ownership model.

Do not choose a cloud service from the deployment demo alone. A demo proves that the happy path exists; an architecture decision must explain day-two change, degraded dependencies, recovery, security evidence, and cost under real load. For AWS IQ, those questions reveal whether the service removes undifferentiated work or merely postpones it.

  • Primary production pattern: Use AWS IQ where finding and engaging AWS-certified experts for scoped cloud projects is on the critical path and the team can own the surrounding controls.
  • Governed shared capability: A platform team can package identity, policy, telemetry, cost allocation, and recovery defaults for multiple consumers.
  • Migration or modernization: Adopt the managed boundary incrementally while preserving data validation, rollback, and an explicit exit path.
Field note 04

Architecture moves that age well

A useful reference architecture is a set of constraints with reasons, not a diagram crowded with service icons. Start with the moves below, assign an owner to each, and encode the ones that can be enforced. Exceptions should include an expiration date and a test that proves why the normal path does not work.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

  • Define the authoritative AWS IQ resource model and provision it from reviewed, versioned configuration.
  • Measure capacity, latency, failure, and cost per engagement, case, recommendation, account, or knowledge contribution under production-shaped load.
  • Separate administrative, deployment, and runtime identities and centralize evidence outside the workload boundary.
  • Test restoration or replacement and document the requirement that would trigger an exit from AWS IQ.
Field note 05

Scaling and performance

AWS IQ capacity should be planned from the arrival rate and shape of each engagement, case, recommendation, account, or knowledge contribution, not from an average utilization graph. Model steady load, bursts, backlog, object or payload size, concurrency, retention, dependency ceilings, and regional quotas. Separate a control-plane request being accepted from capacity becoming usable. Measure provisioning, warm-up, propagation, and recovery time. Where scaling is automatic, set guardrails that protect downstream systems and budgets. Where it is manual, define leading indicators and enough headroom for failure plus deployment overlap.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

Performance tuning must preserve correctness. Optimize the slowest meaningful business path, verify the change against a representative distribution, and watch for work displaced into queues, retries, caches, or operators. With AWS IQ, a lower service-level latency can still create a worse system if downstream saturation, recovery backlog, or cost per completed transaction rises. Keep load-test artifacts and capacity assumptions versioned beside the architecture.

Field note 06

Security and governance

Secure AWS IQ through explicit trust boundaries. Separate human administration, deployment automation, and runtime access; narrow actions and resources; use short-lived credentials; and apply organization guardrails to public exposure, deletion, cross-account sharing, and encryption changes. Protect data in transit and at rest with a documented key model. Send audit and security evidence to a boundary the workload cannot rewrite. Validate untrusted names, payloads, metadata, and configuration even when they arrive through an AWS integration. Treat service-linked roles, resource policies, grants, endpoints, and delegated administration as production code.

Use least privilege as an engineering process, not a one-time IAM document. Begin with separate human, deployment, and runtime identities. Observe required actions, narrow resources and conditions, and add explicit organization guardrails for high-impact operations. Encrypt data in transit and at rest, but also design key ownership, rotation, deletion protection, and break-glass access. Centralize audit records in an account and storage boundary that a compromised workload cannot rewrite.

Threat-model AWS IQ across four surfaces: the management API, the workload’s runtime identity, the network and event inputs that reach it, and the software or configuration artifact that is deployed. Add the data stores and observability pipeline as separate trust boundaries. Preventive controls reduce the reachable state space; detective controls shorten time to evidence; recovery controls make destructive events survivable. A mature design has all three and tests them independently.

Governance should make the secure path faster. Provide approved modules, narrowly scoped roles, standard encryption and logging defaults, ownership tags, and automated evidence. Block dangerous configurations at the organization or pipeline boundary when the intent is unambiguous. Leave application teams enough room to tune the workload without letting every team invent identity, ingress, logging, and incident access from scratch.

Field note 07

Reliability and recovery

Reliability for AWS IQ is the ability to preserve the intended business outcome when a zone, region, dependency, credential, quota, configuration, or operator action fails. Determine which components are regional or zonal and which state is durable, replicated, restorable, or reproducible. Set recovery-time and recovery-point objectives, then build the smallest mechanism that meets them. Test throttling, unavailable capacity, partial completion, duplicate delivery, stale configuration, corrupted input, telemetry loss, and recovery into an isolated environment. A multi-AZ service does not make a single-region or single-account application automatically recoverable.

Define failure in business terms before selecting a recovery mechanism. Availability, durability, recovery time, and recovery point are different objectives. Multi-zone placement improves some infrastructure failures but does not repair corrupt deployments or deleted data. Backups address some data events but do not guarantee a runnable application. Use layered controls: health-based replacement, redundancy, deployment rollback, data protection, quota monitoring, and a rehearsed regional or organizational recovery path where the business requires one.

Write failure-mode tests for AWS IQ before the first serious incident. Include unavailable capacity, throttled control APIs, expired credentials, bad configuration, dependency timeout, partial deployment, telemetry loss, and operator error. Test what happens to in-flight work, how the system detects the condition, who is paged, and how replay or rollback avoids duplicate effects. Recovery time measured in a game day is more credible than recovery time copied from a diagram.

Keep the recovery path simpler than the primary path. If restoration depends on the same identity, network, artifact repository, region, or specialist that the incident removed, it is not independent. Store runbooks where responders can reach them, pre-authorize narrowly scoped emergency actions, and verify backups by restoring into an isolated environment. Record the achieved recovery point and time so business owners can compare evidence with policy.

Field note 08

Cost and capacity economics

Model AWS IQ with a unit that finance and engineering both understand: cost per engagement, case, recommendation, account, or knowledge contribution. Include baseline resources, request or execution charges, storage and retention, logs, network transfer, cross-zone or cross-region movement, encryption and security services, backups, support, licenses, and operator time. Build expected and stress scenarios, attach owners to long-lived resources, and alarm on abnormal unit cost. Remove waste and rightsize before purchasing commitments. Preserve the capacity and retention margins required by the reliability objective instead of treating every idle byte or spare unit as waste.

Evaluate unit economics at the level customers consume: cost per request, job, simulation, tenant, build, or environment. Tagging helps allocation, but architecture determines most spend. Include idle baseline, burst premium, storage growth, log retention, data transfer, support, licenses, and operator time. Rate discounts should follow rightsizing and workload-shape work. A commitment applied to the wrong baseline converts an optimization opportunity into a contract.

Create a cost model for AWS IQ with a low, expected, and stress scenario. Tie every variable to a measurable workload characteristic and identify which team can influence it. Alarm on anomalous unit cost as well as total spend; total spend naturally rises with successful products, while unit cost exposes architectural drift. Review unused capacity and retained artifacts on a schedule, and give every long-lived resource an owner and lifecycle policy.

Optimization should preserve reliability margins. Removing all idle capacity, shortening every retention period, or consolidating every boundary may lower a spreadsheet while increasing incident probability and recovery time. Price the resilience requirement explicitly. Then apply the least risky lever first: eliminate waste, rightsize, improve utilization, reduce unnecessary transfer, select the correct purchasing model, and only then make longer commitments.

Field note 09

Operating it in production

Operate AWS IQ as a product with a named owner, versioned modules, approved defaults, dashboards, runbooks, lifecycle reviews, and an exception process. Monitor customer symptoms and service saturation together. Track change success, quota headroom, access exceptions, failed operations, recovery evidence, spend, and AWS lifecycle announcements. Provide developers a paved contract that hides repetitive configuration without hiding state. Review incidents and near misses monthly until routine replacement, rollback, replay, access recertification, and recovery are boring and evidenced.

Treat configuration as versioned product code. Changes should pass static checks, policy checks, integration tests, and an environment that resembles production. Promote the same artifact; do not rebuild it differently at every stage. Prefer gradual exposure, observable health gates, and automated rollback for reversible changes. For irreversible data or identity changes, use expansion-and-contraction patterns and explicit checkpoints. Record who changed what, why, and which measured signal declared the change safe.

Build one operational view that links AWS IQ health to customer outcomes. Infrastructure metrics explain resources, application metrics explain behavior, traces explain selected paths, and logs provide detailed evidence. None is sufficient alone. Define symptom-based alerts around availability, latency, backlog, freshness, correctness, and saturation; route them to an accountable team; and attach the first diagnostic action. Remove alerts that never change a decision.

Run a monthly service review until the platform is boring. Examine incidents, near misses, failed changes, quota headroom, runtime or image lifecycle, cost per unit, access exceptions, recovery evidence, and support announcements. Convert repeated manual actions into automation only after the team understands the decision being automated. Good operations reduce surprise without hiding state from the people accountable for it.

Field note 10

Failure patterns to avoid

Most expensive mistakes are reasonable shortcuts that survived beyond their original context. Treat these risks as design-review prompts. Ask which control detects each condition, how quickly the team can recover, and whether the workload can be moved or reshaped before the risk becomes a constraint.

A risk register is useful only when it changes action. Give each item an owner, leading indicator, mitigation, and review date. If a risk is accepted, record the business reason. If it is mitigated, test the mitigation. If it is transferred to a managed service, verify the exact responsibility that moved instead of assuming the service name moved all of it.

  • The team assumes AWS IQ transfers application, data, or recovery responsibility that remains with the customer.
  • Automatic scale reaches a quota or overwhelms a downstream dependency before alerts explain the symptom.
  • Manual console changes create drift from the reviewed configuration and weaken incident reconstruction.
  • A lifecycle, pricing, regional, or feature change is discovered only after the architecture depends on it.
Field note 11

Alternatives and the decision

Compare AWS IQ with internal capability, an AWS partner, or a different support plan using the same workload, security assumptions, recovery target, and cost horizon. A managed service can reduce infrastructure labor while increasing product-specific policy, integration, and exit work. Portability of data formats or APIs does not guarantee portability of identity, monitoring, automation, or operating knowledge. The strongest decision states what AWS IQ uniquely contributes, what the organization still owns, and which changed requirement would trigger a different platform.

AWS IQ is a sound choice when the requirement for finding and engaging AWS-certified experts for scoped cloud projects is concrete, the managed boundary is understood, and the team can operate the complete system around it. Start with a production-shaped proof, constrain variation, automate safe defaults, and retain an exit path through portable data, documented configuration, and reproducible artifacts. If the service is marked preview, changing, renamed, or retired, treat availability and lifecycle constraints as first-class architecture inputs rather than documentation footnotes.

Use a short proof of architecture when uncertainty is material. Test the hardest requirement, the most important failure mode, and the expected cost driver—not another hello-world deployment. Compare AWS IQ with the strongest alternative using the same workload and evidence. Record the decision, rejected options, assumptions, migration trigger, and date for review. Architecture remains healthy when a future team can understand both why the choice was correct and which changed fact would make it wrong.

Field note 12

A pragmatic 90-day adoption plan

Days 1–15: define the workload and responsibility map. Capture traffic or job shape, data sensitivity, availability and recovery objectives, latency, unit economics, dependencies, regional constraints, and team ownership. Build a thin threat model and request quota changes early. Select one representative path for the proof, not the easiest path. Establish a clean account, identity, network, artifact, encryption, and logging baseline before application convenience creates permanent exceptions.

Days 16–35: implement a production-shaped walking skeleton on AWS IQ. Provision it from code, deploy an immutable artifact, integrate one real dependency, emit structured telemetry, and prove that a new team member can reproduce the environment. Exercise duplicate work, bad input, dependency timeout, and lost capacity. Measure cold and warm behavior where relevant, saturation, recovery backlog, and cost per successful business unit.

Days 36–60: harden delivery and recovery. Add policy checks, staged promotion, rollback or replacement, least-privilege runtime identity, secret rotation, data protection, retention, and symptom-based alerts. Restore from backup or recreate from artifacts in an isolated environment. Run a game day that includes an operator mistake and a compromised credential. Convert the findings into platform defaults and owned backlog items rather than a slide deck.

Days 61–90: place controlled production load on the service, review evidence with security, finance, and operations, and compare observed behavior with the original decision. Publish a paved-road module, dashboard, runbook, and exception process. Set capacity and cost review thresholds. Finally, write the exit criteria: the scale, feature, compliance need, economics, or organizational change that would trigger a move away from AWS IQ. A reversible decision is easier to make well.

Posted in Customer Enablement | Tagged: , , , , , , , , , , , | Leave a Comment »

AWS IoT TwinMaker Deep Dive: Architecture, Security, Cost & Operations

Posted by Sriram Sanka on August 18, 2026

AWS IoT TwinMaker architecture diagram
AWS IoT TwinMaker architecture and operating-boundary overview.

AWS IoT TwinMaker provides digital-twin entity models, connectors, scenes, and operational dashboards. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Digital-twin entity models, connectors, scenes, and operational dashboards
Primary operating unit: device, connection, message, command, job, signal, or digital-twin entity
Decision boundary: device identity, intermittent networks, fleet updates, telemetry volume, and physical safety
Field note 01

The short version

AWS IoT TwinMaker provides digital-twin entity models, connectors, scenes, and operational dashboards. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Adopt AWS IoT TwinMaker when digital-twin entity models, connectors, scenes, and operational dashboards is an enduring workload requirement and the managed boundary removes work your organization does not need to differentiate. The service decision should be based on measurable behavior and ownership, not catalog breadth. A proof must exercise the hardest integration, the most credible failure, the security boundary, and the dominant unit-cost driver before the design is standardized.

The practical decision is not whether AWS IoT TwinMaker is powerful. It is whether its operating model fits the system and the team. It is best suited to workloads that explicitly need digital-twin entity models, connectors, scenes, and operational dashboards; teams prepared to operate the surrounding identity, network, data, telemetry, delivery, and recovery controls; and platforms that can measure each device, connection, message, command, job, signal, or digital-twin entity. It is usually a poor fit for systems whose requirement can be met by a partner IoT platform or direct application messaging; teams without an accountable service owner; or designs that cannot explain device identity, intermittent networks, fleet updates, telemetry volume, and physical safety before production traffic arrives. That boundary should be written into the architecture decision so later growth does not turn an intentional choice into accidental lock-in.

Field note 02

Build the right mental model

Think of AWS IoT TwinMaker as a managed control plane around each device, connection, message, command, job, signal, or digital-twin entity. The service accepts desired state, policy, configuration, or workload input, then coordinates AWS-owned infrastructure to deliver digital-twin entity models, connectors, scenes, and operational dashboards. The exact managed boundary varies by feature and region, but the architectural pattern is stable: management APIs change configuration, resource policies and IAM decide who may act, service endpoints carry production work, telemetry reports selected behavior, and quotas bound how quickly the system can grow. Customer data, application correctness, access choices, downstream dependencies, and business recovery remain customer concerns even when infrastructure replacement is automated.

A production implementation begins with account and region placement, least-privilege administrative and runtime roles, network reachability, encryption ownership, quotas, logging, tags, and configuration expressed as code. For AWS IoT TwinMaker, define the authoritative resource model, immutable or versioned deployment unit, and the path from a reviewed change to active service behavior. Identify asynchronous operations, eventual consistency, retry semantics, deletion behavior, and every resource created indirectly. Record which actions are safe to repeat, which require a change window, and which can cause data loss or customer-visible interruption.

Separate the control plane from the data plane in both design and incident response. The control plane creates configuration and desired state; the data plane carries production work. A deployment API succeeding does not prove that traffic, jobs, or events are healthy. Conversely, a transient control-plane problem should not automatically stop already-running work. Document which APIs are needed during steady state, which are needed only for change, and which dependencies sit on the critical request path.

Make ownership boundaries visible. Identity, network reachability, encryption keys, artifacts, telemetry, quotas, and billing dimensions frequently belong to different teams. A service can be technically managed while the surrounding system remains unmanaged. Name an owner for the application, the platform configuration, the data, the recovery procedure, and the cost model. That simple map prevents the most common failure mode in cloud programs: assuming an abstraction transferred a responsibility that it only moved.

Field note 03

Where it earns its keep

The strongest AWS IoT TwinMaker architectures begin with a workload whose constraints align with the service. The following patterns are starting points, not product marketing categories. Each still needs an explicit data model, failure model, and ownership model.

Do not choose a cloud service from the deployment demo alone. A demo proves that the happy path exists; an architecture decision must explain day-two change, degraded dependencies, recovery, security evidence, and cost under real load. For AWS IoT TwinMaker, those questions reveal whether the service removes undifferentiated work or merely postpones it.

  • Primary production pattern: Use AWS IoT TwinMaker where digital-twin entity models, connectors, scenes, and operational dashboards is on the critical path and the team can own the surrounding controls.
  • Governed shared capability: A platform team can package identity, policy, telemetry, cost allocation, and recovery defaults for multiple consumers.
  • Migration or modernization: Adopt the managed boundary incrementally while preserving data validation, rollback, and an explicit exit path.
Field note 04

Architecture moves that age well

A useful reference architecture is a set of constraints with reasons, not a diagram crowded with service icons. Start with the moves below, assign an owner to each, and encode the ones that can be enforced. Exceptions should include an expiration date and a test that proves why the normal path does not work.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

  • Define the authoritative AWS IoT TwinMaker resource model and provision it from reviewed, versioned configuration.
  • Measure capacity, latency, failure, and cost per device, connection, message, command, job, signal, or digital-twin entity under production-shaped load.
  • Separate administrative, deployment, and runtime identities and centralize evidence outside the workload boundary.
  • Test restoration or replacement and document the requirement that would trigger an exit from AWS IoT TwinMaker.
Field note 05

Scaling and performance

AWS IoT TwinMaker capacity should be planned from the arrival rate and shape of each device, connection, message, command, job, signal, or digital-twin entity, not from an average utilization graph. Model steady load, bursts, backlog, object or payload size, concurrency, retention, dependency ceilings, and regional quotas. Separate a control-plane request being accepted from capacity becoming usable. Measure provisioning, warm-up, propagation, and recovery time. Where scaling is automatic, set guardrails that protect downstream systems and budgets. Where it is manual, define leading indicators and enough headroom for failure plus deployment overlap.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

Performance tuning must preserve correctness. Optimize the slowest meaningful business path, verify the change against a representative distribution, and watch for work displaced into queues, retries, caches, or operators. With AWS IoT TwinMaker, a lower service-level latency can still create a worse system if downstream saturation, recovery backlog, or cost per completed transaction rises. Keep load-test artifacts and capacity assumptions versioned beside the architecture.

Field note 06

Security and governance

Secure AWS IoT TwinMaker through explicit trust boundaries. Separate human administration, deployment automation, and runtime access; narrow actions and resources; use short-lived credentials; and apply organization guardrails to public exposure, deletion, cross-account sharing, and encryption changes. Protect data in transit and at rest with a documented key model. Send audit and security evidence to a boundary the workload cannot rewrite. Validate untrusted names, payloads, metadata, and configuration even when they arrive through an AWS integration. Treat service-linked roles, resource policies, grants, endpoints, and delegated administration as production code.

Use least privilege as an engineering process, not a one-time IAM document. Begin with separate human, deployment, and runtime identities. Observe required actions, narrow resources and conditions, and add explicit organization guardrails for high-impact operations. Encrypt data in transit and at rest, but also design key ownership, rotation, deletion protection, and break-glass access. Centralize audit records in an account and storage boundary that a compromised workload cannot rewrite.

Threat-model AWS IoT TwinMaker across four surfaces: the management API, the workload’s runtime identity, the network and event inputs that reach it, and the software or configuration artifact that is deployed. Add the data stores and observability pipeline as separate trust boundaries. Preventive controls reduce the reachable state space; detective controls shorten time to evidence; recovery controls make destructive events survivable. A mature design has all three and tests them independently.

Governance should make the secure path faster. Provide approved modules, narrowly scoped roles, standard encryption and logging defaults, ownership tags, and automated evidence. Block dangerous configurations at the organization or pipeline boundary when the intent is unambiguous. Leave application teams enough room to tune the workload without letting every team invent identity, ingress, logging, and incident access from scratch.

Field note 07

Reliability and recovery

Reliability for AWS IoT TwinMaker is the ability to preserve the intended business outcome when a zone, region, dependency, credential, quota, configuration, or operator action fails. Determine which components are regional or zonal and which state is durable, replicated, restorable, or reproducible. Set recovery-time and recovery-point objectives, then build the smallest mechanism that meets them. Test throttling, unavailable capacity, partial completion, duplicate delivery, stale configuration, corrupted input, telemetry loss, and recovery into an isolated environment. A multi-AZ service does not make a single-region or single-account application automatically recoverable.

Define failure in business terms before selecting a recovery mechanism. Availability, durability, recovery time, and recovery point are different objectives. Multi-zone placement improves some infrastructure failures but does not repair corrupt deployments or deleted data. Backups address some data events but do not guarantee a runnable application. Use layered controls: health-based replacement, redundancy, deployment rollback, data protection, quota monitoring, and a rehearsed regional or organizational recovery path where the business requires one.

Write failure-mode tests for AWS IoT TwinMaker before the first serious incident. Include unavailable capacity, throttled control APIs, expired credentials, bad configuration, dependency timeout, partial deployment, telemetry loss, and operator error. Test what happens to in-flight work, how the system detects the condition, who is paged, and how replay or rollback avoids duplicate effects. Recovery time measured in a game day is more credible than recovery time copied from a diagram.

Keep the recovery path simpler than the primary path. If restoration depends on the same identity, network, artifact repository, region, or specialist that the incident removed, it is not independent. Store runbooks where responders can reach them, pre-authorize narrowly scoped emergency actions, and verify backups by restoring into an isolated environment. Record the achieved recovery point and time so business owners can compare evidence with policy.

Field note 08

Cost and capacity economics

Model AWS IoT TwinMaker with a unit that finance and engineering both understand: cost per device, connection, message, command, job, signal, or digital-twin entity. Include baseline resources, request or execution charges, storage and retention, logs, network transfer, cross-zone or cross-region movement, encryption and security services, backups, support, licenses, and operator time. Build expected and stress scenarios, attach owners to long-lived resources, and alarm on abnormal unit cost. Remove waste and rightsize before purchasing commitments. Preserve the capacity and retention margins required by the reliability objective instead of treating every idle byte or spare unit as waste.

Evaluate unit economics at the level customers consume: cost per request, job, simulation, tenant, build, or environment. Tagging helps allocation, but architecture determines most spend. Include idle baseline, burst premium, storage growth, log retention, data transfer, support, licenses, and operator time. Rate discounts should follow rightsizing and workload-shape work. A commitment applied to the wrong baseline converts an optimization opportunity into a contract.

Create a cost model for AWS IoT TwinMaker with a low, expected, and stress scenario. Tie every variable to a measurable workload characteristic and identify which team can influence it. Alarm on anomalous unit cost as well as total spend; total spend naturally rises with successful products, while unit cost exposes architectural drift. Review unused capacity and retained artifacts on a schedule, and give every long-lived resource an owner and lifecycle policy.

Optimization should preserve reliability margins. Removing all idle capacity, shortening every retention period, or consolidating every boundary may lower a spreadsheet while increasing incident probability and recovery time. Price the resilience requirement explicitly. Then apply the least risky lever first: eliminate waste, rightsize, improve utilization, reduce unnecessary transfer, select the correct purchasing model, and only then make longer commitments.

Field note 09

Operating it in production

Operate AWS IoT TwinMaker as a product with a named owner, versioned modules, approved defaults, dashboards, runbooks, lifecycle reviews, and an exception process. Monitor customer symptoms and service saturation together. Track change success, quota headroom, access exceptions, failed operations, recovery evidence, spend, and AWS lifecycle announcements. Provide developers a paved contract that hides repetitive configuration without hiding state. Review incidents and near misses monthly until routine replacement, rollback, replay, access recertification, and recovery are boring and evidenced.

Treat configuration as versioned product code. Changes should pass static checks, policy checks, integration tests, and an environment that resembles production. Promote the same artifact; do not rebuild it differently at every stage. Prefer gradual exposure, observable health gates, and automated rollback for reversible changes. For irreversible data or identity changes, use expansion-and-contraction patterns and explicit checkpoints. Record who changed what, why, and which measured signal declared the change safe.

Build one operational view that links AWS IoT TwinMaker health to customer outcomes. Infrastructure metrics explain resources, application metrics explain behavior, traces explain selected paths, and logs provide detailed evidence. None is sufficient alone. Define symptom-based alerts around availability, latency, backlog, freshness, correctness, and saturation; route them to an accountable team; and attach the first diagnostic action. Remove alerts that never change a decision.

Run a monthly service review until the platform is boring. Examine incidents, near misses, failed changes, quota headroom, runtime or image lifecycle, cost per unit, access exceptions, recovery evidence, and support announcements. Convert repeated manual actions into automation only after the team understands the decision being automated. Good operations reduce surprise without hiding state from the people accountable for it.

Field note 10

Failure patterns to avoid

Most expensive mistakes are reasonable shortcuts that survived beyond their original context. Treat these risks as design-review prompts. Ask which control detects each condition, how quickly the team can recover, and whether the workload can be moved or reshaped before the risk becomes a constraint.

A risk register is useful only when it changes action. Give each item an owner, leading indicator, mitigation, and review date. If a risk is accepted, record the business reason. If it is mitigated, test the mitigation. If it is transferred to a managed service, verify the exact responsibility that moved instead of assuming the service name moved all of it.

  • The team assumes AWS IoT TwinMaker transfers application, data, or recovery responsibility that remains with the customer.
  • Automatic scale reaches a quota or overwhelms a downstream dependency before alerts explain the symptom.
  • Manual console changes create drift from the reviewed configuration and weaken incident reconstruction.
  • A lifecycle, pricing, regional, or feature change is discovered only after the architecture depends on it.
Field note 11

Alternatives and the decision

Compare AWS IoT TwinMaker with a partner IoT platform or direct application messaging using the same workload, security assumptions, recovery target, and cost horizon. A managed service can reduce infrastructure labor while increasing product-specific policy, integration, and exit work. Portability of data formats or APIs does not guarantee portability of identity, monitoring, automation, or operating knowledge. The strongest decision states what AWS IoT TwinMaker uniquely contributes, what the organization still owns, and which changed requirement would trigger a different platform.

AWS IoT TwinMaker is a sound choice when the requirement for digital-twin entity models, connectors, scenes, and operational dashboards is concrete, the managed boundary is understood, and the team can operate the complete system around it. Start with a production-shaped proof, constrain variation, automate safe defaults, and retain an exit path through portable data, documented configuration, and reproducible artifacts. If the service is marked preview, changing, renamed, or retired, treat availability and lifecycle constraints as first-class architecture inputs rather than documentation footnotes.

Use a short proof of architecture when uncertainty is material. Test the hardest requirement, the most important failure mode, and the expected cost driver—not another hello-world deployment. Compare AWS IoT TwinMaker with the strongest alternative using the same workload and evidence. Record the decision, rejected options, assumptions, migration trigger, and date for review. Architecture remains healthy when a future team can understand both why the choice was correct and which changed fact would make it wrong.

Field note 12

A pragmatic 90-day adoption plan

Days 1–15: define the workload and responsibility map. Capture traffic or job shape, data sensitivity, availability and recovery objectives, latency, unit economics, dependencies, regional constraints, and team ownership. Build a thin threat model and request quota changes early. Select one representative path for the proof, not the easiest path. Establish a clean account, identity, network, artifact, encryption, and logging baseline before application convenience creates permanent exceptions.

Days 16–35: implement a production-shaped walking skeleton on AWS IoT TwinMaker. Provision it from code, deploy an immutable artifact, integrate one real dependency, emit structured telemetry, and prove that a new team member can reproduce the environment. Exercise duplicate work, bad input, dependency timeout, and lost capacity. Measure cold and warm behavior where relevant, saturation, recovery backlog, and cost per successful business unit.

Days 36–60: harden delivery and recovery. Add policy checks, staged promotion, rollback or replacement, least-privilege runtime identity, secret rotation, data protection, retention, and symptom-based alerts. Restore from backup or recreate from artifacts in an isolated environment. Run a game day that includes an operator mistake and a compromised credential. Convert the findings into platform defaults and owned backlog items rather than a slide deck.

Days 61–90: place controlled production load on the service, review evidence with security, finance, and operations, and compare observed behavior with the original decision. Publish a paved-road module, dashboard, runbook, and exception process. Set capacity and cost review thresholds. Finally, write the exit criteria: the scale, feature, compliance need, economics, or organizational change that would trigger a move away from AWS IoT TwinMaker. A reversible decision is easier to make well.

Posted in Internet of Things | Tagged: , , , , , , , , , , , | Leave a Comment »

AWS IoT SiteWise Deep Dive: Architecture, Security, Cost & Operations

Posted by Sriram Sanka on August 18, 2026

AWS IoT SiteWise architecture diagram
AWS IoT SiteWise architecture and operating-boundary overview.

AWS IoT SiteWise provides industrial equipment modeling, ingestion, metrics, and operational portals. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Industrial equipment modeling, ingestion, metrics, and operational portals
Primary operating unit: device, connection, message, command, job, signal, or digital-twin entity
Decision boundary: device identity, intermittent networks, fleet updates, telemetry volume, and physical safety
Field note 01

The short version

AWS IoT SiteWise provides industrial equipment modeling, ingestion, metrics, and operational portals. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Adopt AWS IoT SiteWise when industrial equipment modeling, ingestion, metrics, and operational portals is an enduring workload requirement and the managed boundary removes work your organization does not need to differentiate. The service decision should be based on measurable behavior and ownership, not catalog breadth. A proof must exercise the hardest integration, the most credible failure, the security boundary, and the dominant unit-cost driver before the design is standardized.

The practical decision is not whether AWS IoT SiteWise is powerful. It is whether its operating model fits the system and the team. It is best suited to workloads that explicitly need industrial equipment modeling, ingestion, metrics, and operational portals; teams prepared to operate the surrounding identity, network, data, telemetry, delivery, and recovery controls; and platforms that can measure each device, connection, message, command, job, signal, or digital-twin entity. It is usually a poor fit for systems whose requirement can be met by a partner IoT platform or direct application messaging; teams without an accountable service owner; or designs that cannot explain device identity, intermittent networks, fleet updates, telemetry volume, and physical safety before production traffic arrives. That boundary should be written into the architecture decision so later growth does not turn an intentional choice into accidental lock-in.

Field note 02

Build the right mental model

Think of AWS IoT SiteWise as a managed control plane around each device, connection, message, command, job, signal, or digital-twin entity. The service accepts desired state, policy, configuration, or workload input, then coordinates AWS-owned infrastructure to deliver industrial equipment modeling, ingestion, metrics, and operational portals. The exact managed boundary varies by feature and region, but the architectural pattern is stable: management APIs change configuration, resource policies and IAM decide who may act, service endpoints carry production work, telemetry reports selected behavior, and quotas bound how quickly the system can grow. Customer data, application correctness, access choices, downstream dependencies, and business recovery remain customer concerns even when infrastructure replacement is automated.

A production implementation begins with account and region placement, least-privilege administrative and runtime roles, network reachability, encryption ownership, quotas, logging, tags, and configuration expressed as code. For AWS IoT SiteWise, define the authoritative resource model, immutable or versioned deployment unit, and the path from a reviewed change to active service behavior. Identify asynchronous operations, eventual consistency, retry semantics, deletion behavior, and every resource created indirectly. Record which actions are safe to repeat, which require a change window, and which can cause data loss or customer-visible interruption.

Separate the control plane from the data plane in both design and incident response. The control plane creates configuration and desired state; the data plane carries production work. A deployment API succeeding does not prove that traffic, jobs, or events are healthy. Conversely, a transient control-plane problem should not automatically stop already-running work. Document which APIs are needed during steady state, which are needed only for change, and which dependencies sit on the critical request path.

Make ownership boundaries visible. Identity, network reachability, encryption keys, artifacts, telemetry, quotas, and billing dimensions frequently belong to different teams. A service can be technically managed while the surrounding system remains unmanaged. Name an owner for the application, the platform configuration, the data, the recovery procedure, and the cost model. That simple map prevents the most common failure mode in cloud programs: assuming an abstraction transferred a responsibility that it only moved.

Field note 03

Where it earns its keep

The strongest AWS IoT SiteWise architectures begin with a workload whose constraints align with the service. The following patterns are starting points, not product marketing categories. Each still needs an explicit data model, failure model, and ownership model.

Do not choose a cloud service from the deployment demo alone. A demo proves that the happy path exists; an architecture decision must explain day-two change, degraded dependencies, recovery, security evidence, and cost under real load. For AWS IoT SiteWise, those questions reveal whether the service removes undifferentiated work or merely postpones it.

  • Primary production pattern: Use AWS IoT SiteWise where industrial equipment modeling, ingestion, metrics, and operational portals is on the critical path and the team can own the surrounding controls.
  • Governed shared capability: A platform team can package identity, policy, telemetry, cost allocation, and recovery defaults for multiple consumers.
  • Migration or modernization: Adopt the managed boundary incrementally while preserving data validation, rollback, and an explicit exit path.
Field note 04

Architecture moves that age well

A useful reference architecture is a set of constraints with reasons, not a diagram crowded with service icons. Start with the moves below, assign an owner to each, and encode the ones that can be enforced. Exceptions should include an expiration date and a test that proves why the normal path does not work.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

  • Define the authoritative AWS IoT SiteWise resource model and provision it from reviewed, versioned configuration.
  • Measure capacity, latency, failure, and cost per device, connection, message, command, job, signal, or digital-twin entity under production-shaped load.
  • Separate administrative, deployment, and runtime identities and centralize evidence outside the workload boundary.
  • Test restoration or replacement and document the requirement that would trigger an exit from AWS IoT SiteWise.
Field note 05

Scaling and performance

AWS IoT SiteWise capacity should be planned from the arrival rate and shape of each device, connection, message, command, job, signal, or digital-twin entity, not from an average utilization graph. Model steady load, bursts, backlog, object or payload size, concurrency, retention, dependency ceilings, and regional quotas. Separate a control-plane request being accepted from capacity becoming usable. Measure provisioning, warm-up, propagation, and recovery time. Where scaling is automatic, set guardrails that protect downstream systems and budgets. Where it is manual, define leading indicators and enough headroom for failure plus deployment overlap.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

Performance tuning must preserve correctness. Optimize the slowest meaningful business path, verify the change against a representative distribution, and watch for work displaced into queues, retries, caches, or operators. With AWS IoT SiteWise, a lower service-level latency can still create a worse system if downstream saturation, recovery backlog, or cost per completed transaction rises. Keep load-test artifacts and capacity assumptions versioned beside the architecture.

Field note 06

Security and governance

Secure AWS IoT SiteWise through explicit trust boundaries. Separate human administration, deployment automation, and runtime access; narrow actions and resources; use short-lived credentials; and apply organization guardrails to public exposure, deletion, cross-account sharing, and encryption changes. Protect data in transit and at rest with a documented key model. Send audit and security evidence to a boundary the workload cannot rewrite. Validate untrusted names, payloads, metadata, and configuration even when they arrive through an AWS integration. Treat service-linked roles, resource policies, grants, endpoints, and delegated administration as production code.

Use least privilege as an engineering process, not a one-time IAM document. Begin with separate human, deployment, and runtime identities. Observe required actions, narrow resources and conditions, and add explicit organization guardrails for high-impact operations. Encrypt data in transit and at rest, but also design key ownership, rotation, deletion protection, and break-glass access. Centralize audit records in an account and storage boundary that a compromised workload cannot rewrite.

Threat-model AWS IoT SiteWise across four surfaces: the management API, the workload’s runtime identity, the network and event inputs that reach it, and the software or configuration artifact that is deployed. Add the data stores and observability pipeline as separate trust boundaries. Preventive controls reduce the reachable state space; detective controls shorten time to evidence; recovery controls make destructive events survivable. A mature design has all three and tests them independently.

Governance should make the secure path faster. Provide approved modules, narrowly scoped roles, standard encryption and logging defaults, ownership tags, and automated evidence. Block dangerous configurations at the organization or pipeline boundary when the intent is unambiguous. Leave application teams enough room to tune the workload without letting every team invent identity, ingress, logging, and incident access from scratch.

Field note 07

Reliability and recovery

Reliability for AWS IoT SiteWise is the ability to preserve the intended business outcome when a zone, region, dependency, credential, quota, configuration, or operator action fails. Determine which components are regional or zonal and which state is durable, replicated, restorable, or reproducible. Set recovery-time and recovery-point objectives, then build the smallest mechanism that meets them. Test throttling, unavailable capacity, partial completion, duplicate delivery, stale configuration, corrupted input, telemetry loss, and recovery into an isolated environment. A multi-AZ service does not make a single-region or single-account application automatically recoverable.

Define failure in business terms before selecting a recovery mechanism. Availability, durability, recovery time, and recovery point are different objectives. Multi-zone placement improves some infrastructure failures but does not repair corrupt deployments or deleted data. Backups address some data events but do not guarantee a runnable application. Use layered controls: health-based replacement, redundancy, deployment rollback, data protection, quota monitoring, and a rehearsed regional or organizational recovery path where the business requires one.

Write failure-mode tests for AWS IoT SiteWise before the first serious incident. Include unavailable capacity, throttled control APIs, expired credentials, bad configuration, dependency timeout, partial deployment, telemetry loss, and operator error. Test what happens to in-flight work, how the system detects the condition, who is paged, and how replay or rollback avoids duplicate effects. Recovery time measured in a game day is more credible than recovery time copied from a diagram.

Keep the recovery path simpler than the primary path. If restoration depends on the same identity, network, artifact repository, region, or specialist that the incident removed, it is not independent. Store runbooks where responders can reach them, pre-authorize narrowly scoped emergency actions, and verify backups by restoring into an isolated environment. Record the achieved recovery point and time so business owners can compare evidence with policy.

Field note 08

Cost and capacity economics

Model AWS IoT SiteWise with a unit that finance and engineering both understand: cost per device, connection, message, command, job, signal, or digital-twin entity. Include baseline resources, request or execution charges, storage and retention, logs, network transfer, cross-zone or cross-region movement, encryption and security services, backups, support, licenses, and operator time. Build expected and stress scenarios, attach owners to long-lived resources, and alarm on abnormal unit cost. Remove waste and rightsize before purchasing commitments. Preserve the capacity and retention margins required by the reliability objective instead of treating every idle byte or spare unit as waste.

Evaluate unit economics at the level customers consume: cost per request, job, simulation, tenant, build, or environment. Tagging helps allocation, but architecture determines most spend. Include idle baseline, burst premium, storage growth, log retention, data transfer, support, licenses, and operator time. Rate discounts should follow rightsizing and workload-shape work. A commitment applied to the wrong baseline converts an optimization opportunity into a contract.

Create a cost model for AWS IoT SiteWise with a low, expected, and stress scenario. Tie every variable to a measurable workload characteristic and identify which team can influence it. Alarm on anomalous unit cost as well as total spend; total spend naturally rises with successful products, while unit cost exposes architectural drift. Review unused capacity and retained artifacts on a schedule, and give every long-lived resource an owner and lifecycle policy.

Optimization should preserve reliability margins. Removing all idle capacity, shortening every retention period, or consolidating every boundary may lower a spreadsheet while increasing incident probability and recovery time. Price the resilience requirement explicitly. Then apply the least risky lever first: eliminate waste, rightsize, improve utilization, reduce unnecessary transfer, select the correct purchasing model, and only then make longer commitments.

Field note 09

Operating it in production

Operate AWS IoT SiteWise as a product with a named owner, versioned modules, approved defaults, dashboards, runbooks, lifecycle reviews, and an exception process. Monitor customer symptoms and service saturation together. Track change success, quota headroom, access exceptions, failed operations, recovery evidence, spend, and AWS lifecycle announcements. Provide developers a paved contract that hides repetitive configuration without hiding state. Review incidents and near misses monthly until routine replacement, rollback, replay, access recertification, and recovery are boring and evidenced.

Treat configuration as versioned product code. Changes should pass static checks, policy checks, integration tests, and an environment that resembles production. Promote the same artifact; do not rebuild it differently at every stage. Prefer gradual exposure, observable health gates, and automated rollback for reversible changes. For irreversible data or identity changes, use expansion-and-contraction patterns and explicit checkpoints. Record who changed what, why, and which measured signal declared the change safe.

Build one operational view that links AWS IoT SiteWise health to customer outcomes. Infrastructure metrics explain resources, application metrics explain behavior, traces explain selected paths, and logs provide detailed evidence. None is sufficient alone. Define symptom-based alerts around availability, latency, backlog, freshness, correctness, and saturation; route them to an accountable team; and attach the first diagnostic action. Remove alerts that never change a decision.

Run a monthly service review until the platform is boring. Examine incidents, near misses, failed changes, quota headroom, runtime or image lifecycle, cost per unit, access exceptions, recovery evidence, and support announcements. Convert repeated manual actions into automation only after the team understands the decision being automated. Good operations reduce surprise without hiding state from the people accountable for it.

Field note 10

Failure patterns to avoid

Most expensive mistakes are reasonable shortcuts that survived beyond their original context. Treat these risks as design-review prompts. Ask which control detects each condition, how quickly the team can recover, and whether the workload can be moved or reshaped before the risk becomes a constraint.

A risk register is useful only when it changes action. Give each item an owner, leading indicator, mitigation, and review date. If a risk is accepted, record the business reason. If it is mitigated, test the mitigation. If it is transferred to a managed service, verify the exact responsibility that moved instead of assuming the service name moved all of it.

  • The team assumes AWS IoT SiteWise transfers application, data, or recovery responsibility that remains with the customer.
  • Automatic scale reaches a quota or overwhelms a downstream dependency before alerts explain the symptom.
  • Manual console changes create drift from the reviewed configuration and weaken incident reconstruction.
  • A lifecycle, pricing, regional, or feature change is discovered only after the architecture depends on it.
Field note 11

Alternatives and the decision

Compare AWS IoT SiteWise with a partner IoT platform or direct application messaging using the same workload, security assumptions, recovery target, and cost horizon. A managed service can reduce infrastructure labor while increasing product-specific policy, integration, and exit work. Portability of data formats or APIs does not guarantee portability of identity, monitoring, automation, or operating knowledge. The strongest decision states what AWS IoT SiteWise uniquely contributes, what the organization still owns, and which changed requirement would trigger a different platform.

AWS IoT SiteWise is a sound choice when the requirement for industrial equipment modeling, ingestion, metrics, and operational portals is concrete, the managed boundary is understood, and the team can operate the complete system around it. Start with a production-shaped proof, constrain variation, automate safe defaults, and retain an exit path through portable data, documented configuration, and reproducible artifacts. If the service is marked preview, changing, renamed, or retired, treat availability and lifecycle constraints as first-class architecture inputs rather than documentation footnotes.

Use a short proof of architecture when uncertainty is material. Test the hardest requirement, the most important failure mode, and the expected cost driver—not another hello-world deployment. Compare AWS IoT SiteWise with the strongest alternative using the same workload and evidence. Record the decision, rejected options, assumptions, migration trigger, and date for review. Architecture remains healthy when a future team can understand both why the choice was correct and which changed fact would make it wrong.

Field note 12

A pragmatic 90-day adoption plan

Days 1–15: define the workload and responsibility map. Capture traffic or job shape, data sensitivity, availability and recovery objectives, latency, unit economics, dependencies, regional constraints, and team ownership. Build a thin threat model and request quota changes early. Select one representative path for the proof, not the easiest path. Establish a clean account, identity, network, artifact, encryption, and logging baseline before application convenience creates permanent exceptions.

Days 16–35: implement a production-shaped walking skeleton on AWS IoT SiteWise. Provision it from code, deploy an immutable artifact, integrate one real dependency, emit structured telemetry, and prove that a new team member can reproduce the environment. Exercise duplicate work, bad input, dependency timeout, and lost capacity. Measure cold and warm behavior where relevant, saturation, recovery backlog, and cost per successful business unit.

Days 36–60: harden delivery and recovery. Add policy checks, staged promotion, rollback or replacement, least-privilege runtime identity, secret rotation, data protection, retention, and symptom-based alerts. Restore from backup or recreate from artifacts in an isolated environment. Run a game day that includes an operator mistake and a compromised credential. Convert the findings into platform defaults and owned backlog items rather than a slide deck.

Days 61–90: place controlled production load on the service, review evidence with security, finance, and operations, and compare observed behavior with the original decision. Publish a paved-road module, dashboard, runbook, and exception process. Set capacity and cost review thresholds. Finally, write the exit criteria: the scale, feature, compliance need, economics, or organizational change that would trigger a move away from AWS IoT SiteWise. A reversible decision is easier to make well.

Posted in Internet of Things | Tagged: , , , , , , , , , , , | Leave a Comment »

AWS IoT Greengrass Deep Dive: Architecture, Security, Cost & Operations

Posted by Sriram Sanka on August 18, 2026

AWS IoT Greengrass architecture diagram
AWS IoT Greengrass architecture and operating-boundary overview.

AWS IoT Greengrass provides edge components, local messaging, deployments, and cloud synchronization. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Edge components, local messaging, deployments, and cloud synchronization
Primary operating unit: device, connection, message, command, job, signal, or digital-twin entity
Decision boundary: device identity, intermittent networks, fleet updates, telemetry volume, and physical safety
Field note 01

The short version

AWS IoT Greengrass provides edge components, local messaging, deployments, and cloud synchronization. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Adopt AWS IoT Greengrass when edge components, local messaging, deployments, and cloud synchronization is an enduring workload requirement and the managed boundary removes work your organization does not need to differentiate. The service decision should be based on measurable behavior and ownership, not catalog breadth. A proof must exercise the hardest integration, the most credible failure, the security boundary, and the dominant unit-cost driver before the design is standardized.

The practical decision is not whether AWS IoT Greengrass is powerful. It is whether its operating model fits the system and the team. It is best suited to workloads that explicitly need edge components, local messaging, deployments, and cloud synchronization; teams prepared to operate the surrounding identity, network, data, telemetry, delivery, and recovery controls; and platforms that can measure each device, connection, message, command, job, signal, or digital-twin entity. It is usually a poor fit for systems whose requirement can be met by a partner IoT platform or direct application messaging; teams without an accountable service owner; or designs that cannot explain device identity, intermittent networks, fleet updates, telemetry volume, and physical safety before production traffic arrives. That boundary should be written into the architecture decision so later growth does not turn an intentional choice into accidental lock-in.

Field note 02

Build the right mental model

Think of AWS IoT Greengrass as a managed control plane around each device, connection, message, command, job, signal, or digital-twin entity. The service accepts desired state, policy, configuration, or workload input, then coordinates AWS-owned infrastructure to deliver edge components, local messaging, deployments, and cloud synchronization. The exact managed boundary varies by feature and region, but the architectural pattern is stable: management APIs change configuration, resource policies and IAM decide who may act, service endpoints carry production work, telemetry reports selected behavior, and quotas bound how quickly the system can grow. Customer data, application correctness, access choices, downstream dependencies, and business recovery remain customer concerns even when infrastructure replacement is automated.

A production implementation begins with account and region placement, least-privilege administrative and runtime roles, network reachability, encryption ownership, quotas, logging, tags, and configuration expressed as code. For AWS IoT Greengrass, define the authoritative resource model, immutable or versioned deployment unit, and the path from a reviewed change to active service behavior. Identify asynchronous operations, eventual consistency, retry semantics, deletion behavior, and every resource created indirectly. Record which actions are safe to repeat, which require a change window, and which can cause data loss or customer-visible interruption.

Separate the control plane from the data plane in both design and incident response. The control plane creates configuration and desired state; the data plane carries production work. A deployment API succeeding does not prove that traffic, jobs, or events are healthy. Conversely, a transient control-plane problem should not automatically stop already-running work. Document which APIs are needed during steady state, which are needed only for change, and which dependencies sit on the critical request path.

Make ownership boundaries visible. Identity, network reachability, encryption keys, artifacts, telemetry, quotas, and billing dimensions frequently belong to different teams. A service can be technically managed while the surrounding system remains unmanaged. Name an owner for the application, the platform configuration, the data, the recovery procedure, and the cost model. That simple map prevents the most common failure mode in cloud programs: assuming an abstraction transferred a responsibility that it only moved.

Field note 03

Where it earns its keep

The strongest AWS IoT Greengrass architectures begin with a workload whose constraints align with the service. The following patterns are starting points, not product marketing categories. Each still needs an explicit data model, failure model, and ownership model.

Do not choose a cloud service from the deployment demo alone. A demo proves that the happy path exists; an architecture decision must explain day-two change, degraded dependencies, recovery, security evidence, and cost under real load. For AWS IoT Greengrass, those questions reveal whether the service removes undifferentiated work or merely postpones it.

  • Primary production pattern: Use AWS IoT Greengrass where edge components, local messaging, deployments, and cloud synchronization is on the critical path and the team can own the surrounding controls.
  • Governed shared capability: A platform team can package identity, policy, telemetry, cost allocation, and recovery defaults for multiple consumers.
  • Migration or modernization: Adopt the managed boundary incrementally while preserving data validation, rollback, and an explicit exit path.
Field note 04

Architecture moves that age well

A useful reference architecture is a set of constraints with reasons, not a diagram crowded with service icons. Start with the moves below, assign an owner to each, and encode the ones that can be enforced. Exceptions should include an expiration date and a test that proves why the normal path does not work.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

  • Define the authoritative AWS IoT Greengrass resource model and provision it from reviewed, versioned configuration.
  • Measure capacity, latency, failure, and cost per device, connection, message, command, job, signal, or digital-twin entity under production-shaped load.
  • Separate administrative, deployment, and runtime identities and centralize evidence outside the workload boundary.
  • Test restoration or replacement and document the requirement that would trigger an exit from AWS IoT Greengrass.
Field note 05

Scaling and performance

AWS IoT Greengrass capacity should be planned from the arrival rate and shape of each device, connection, message, command, job, signal, or digital-twin entity, not from an average utilization graph. Model steady load, bursts, backlog, object or payload size, concurrency, retention, dependency ceilings, and regional quotas. Separate a control-plane request being accepted from capacity becoming usable. Measure provisioning, warm-up, propagation, and recovery time. Where scaling is automatic, set guardrails that protect downstream systems and budgets. Where it is manual, define leading indicators and enough headroom for failure plus deployment overlap.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

Performance tuning must preserve correctness. Optimize the slowest meaningful business path, verify the change against a representative distribution, and watch for work displaced into queues, retries, caches, or operators. With AWS IoT Greengrass, a lower service-level latency can still create a worse system if downstream saturation, recovery backlog, or cost per completed transaction rises. Keep load-test artifacts and capacity assumptions versioned beside the architecture.

Field note 06

Security and governance

Secure AWS IoT Greengrass through explicit trust boundaries. Separate human administration, deployment automation, and runtime access; narrow actions and resources; use short-lived credentials; and apply organization guardrails to public exposure, deletion, cross-account sharing, and encryption changes. Protect data in transit and at rest with a documented key model. Send audit and security evidence to a boundary the workload cannot rewrite. Validate untrusted names, payloads, metadata, and configuration even when they arrive through an AWS integration. Treat service-linked roles, resource policies, grants, endpoints, and delegated administration as production code.

Use least privilege as an engineering process, not a one-time IAM document. Begin with separate human, deployment, and runtime identities. Observe required actions, narrow resources and conditions, and add explicit organization guardrails for high-impact operations. Encrypt data in transit and at rest, but also design key ownership, rotation, deletion protection, and break-glass access. Centralize audit records in an account and storage boundary that a compromised workload cannot rewrite.

Threat-model AWS IoT Greengrass across four surfaces: the management API, the workload’s runtime identity, the network and event inputs that reach it, and the software or configuration artifact that is deployed. Add the data stores and observability pipeline as separate trust boundaries. Preventive controls reduce the reachable state space; detective controls shorten time to evidence; recovery controls make destructive events survivable. A mature design has all three and tests them independently.

Governance should make the secure path faster. Provide approved modules, narrowly scoped roles, standard encryption and logging defaults, ownership tags, and automated evidence. Block dangerous configurations at the organization or pipeline boundary when the intent is unambiguous. Leave application teams enough room to tune the workload without letting every team invent identity, ingress, logging, and incident access from scratch.

Field note 07

Reliability and recovery

Reliability for AWS IoT Greengrass is the ability to preserve the intended business outcome when a zone, region, dependency, credential, quota, configuration, or operator action fails. Determine which components are regional or zonal and which state is durable, replicated, restorable, or reproducible. Set recovery-time and recovery-point objectives, then build the smallest mechanism that meets them. Test throttling, unavailable capacity, partial completion, duplicate delivery, stale configuration, corrupted input, telemetry loss, and recovery into an isolated environment. A multi-AZ service does not make a single-region or single-account application automatically recoverable.

Define failure in business terms before selecting a recovery mechanism. Availability, durability, recovery time, and recovery point are different objectives. Multi-zone placement improves some infrastructure failures but does not repair corrupt deployments or deleted data. Backups address some data events but do not guarantee a runnable application. Use layered controls: health-based replacement, redundancy, deployment rollback, data protection, quota monitoring, and a rehearsed regional or organizational recovery path where the business requires one.

Write failure-mode tests for AWS IoT Greengrass before the first serious incident. Include unavailable capacity, throttled control APIs, expired credentials, bad configuration, dependency timeout, partial deployment, telemetry loss, and operator error. Test what happens to in-flight work, how the system detects the condition, who is paged, and how replay or rollback avoids duplicate effects. Recovery time measured in a game day is more credible than recovery time copied from a diagram.

Keep the recovery path simpler than the primary path. If restoration depends on the same identity, network, artifact repository, region, or specialist that the incident removed, it is not independent. Store runbooks where responders can reach them, pre-authorize narrowly scoped emergency actions, and verify backups by restoring into an isolated environment. Record the achieved recovery point and time so business owners can compare evidence with policy.

Field note 08

Cost and capacity economics

Model AWS IoT Greengrass with a unit that finance and engineering both understand: cost per device, connection, message, command, job, signal, or digital-twin entity. Include baseline resources, request or execution charges, storage and retention, logs, network transfer, cross-zone or cross-region movement, encryption and security services, backups, support, licenses, and operator time. Build expected and stress scenarios, attach owners to long-lived resources, and alarm on abnormal unit cost. Remove waste and rightsize before purchasing commitments. Preserve the capacity and retention margins required by the reliability objective instead of treating every idle byte or spare unit as waste.

Evaluate unit economics at the level customers consume: cost per request, job, simulation, tenant, build, or environment. Tagging helps allocation, but architecture determines most spend. Include idle baseline, burst premium, storage growth, log retention, data transfer, support, licenses, and operator time. Rate discounts should follow rightsizing and workload-shape work. A commitment applied to the wrong baseline converts an optimization opportunity into a contract.

Create a cost model for AWS IoT Greengrass with a low, expected, and stress scenario. Tie every variable to a measurable workload characteristic and identify which team can influence it. Alarm on anomalous unit cost as well as total spend; total spend naturally rises with successful products, while unit cost exposes architectural drift. Review unused capacity and retained artifacts on a schedule, and give every long-lived resource an owner and lifecycle policy.

Optimization should preserve reliability margins. Removing all idle capacity, shortening every retention period, or consolidating every boundary may lower a spreadsheet while increasing incident probability and recovery time. Price the resilience requirement explicitly. Then apply the least risky lever first: eliminate waste, rightsize, improve utilization, reduce unnecessary transfer, select the correct purchasing model, and only then make longer commitments.

Field note 09

Operating it in production

Operate AWS IoT Greengrass as a product with a named owner, versioned modules, approved defaults, dashboards, runbooks, lifecycle reviews, and an exception process. Monitor customer symptoms and service saturation together. Track change success, quota headroom, access exceptions, failed operations, recovery evidence, spend, and AWS lifecycle announcements. Provide developers a paved contract that hides repetitive configuration without hiding state. Review incidents and near misses monthly until routine replacement, rollback, replay, access recertification, and recovery are boring and evidenced.

Treat configuration as versioned product code. Changes should pass static checks, policy checks, integration tests, and an environment that resembles production. Promote the same artifact; do not rebuild it differently at every stage. Prefer gradual exposure, observable health gates, and automated rollback for reversible changes. For irreversible data or identity changes, use expansion-and-contraction patterns and explicit checkpoints. Record who changed what, why, and which measured signal declared the change safe.

Build one operational view that links AWS IoT Greengrass health to customer outcomes. Infrastructure metrics explain resources, application metrics explain behavior, traces explain selected paths, and logs provide detailed evidence. None is sufficient alone. Define symptom-based alerts around availability, latency, backlog, freshness, correctness, and saturation; route them to an accountable team; and attach the first diagnostic action. Remove alerts that never change a decision.

Run a monthly service review until the platform is boring. Examine incidents, near misses, failed changes, quota headroom, runtime or image lifecycle, cost per unit, access exceptions, recovery evidence, and support announcements. Convert repeated manual actions into automation only after the team understands the decision being automated. Good operations reduce surprise without hiding state from the people accountable for it.

Field note 10

Failure patterns to avoid

Most expensive mistakes are reasonable shortcuts that survived beyond their original context. Treat these risks as design-review prompts. Ask which control detects each condition, how quickly the team can recover, and whether the workload can be moved or reshaped before the risk becomes a constraint.

A risk register is useful only when it changes action. Give each item an owner, leading indicator, mitigation, and review date. If a risk is accepted, record the business reason. If it is mitigated, test the mitigation. If it is transferred to a managed service, verify the exact responsibility that moved instead of assuming the service name moved all of it.

  • The team assumes AWS IoT Greengrass transfers application, data, or recovery responsibility that remains with the customer.
  • Automatic scale reaches a quota or overwhelms a downstream dependency before alerts explain the symptom.
  • Manual console changes create drift from the reviewed configuration and weaken incident reconstruction.
  • A lifecycle, pricing, regional, or feature change is discovered only after the architecture depends on it.
Field note 11

Alternatives and the decision

Compare AWS IoT Greengrass with a partner IoT platform or direct application messaging using the same workload, security assumptions, recovery target, and cost horizon. A managed service can reduce infrastructure labor while increasing product-specific policy, integration, and exit work. Portability of data formats or APIs does not guarantee portability of identity, monitoring, automation, or operating knowledge. The strongest decision states what AWS IoT Greengrass uniquely contributes, what the organization still owns, and which changed requirement would trigger a different platform.

AWS IoT Greengrass is a sound choice when the requirement for edge components, local messaging, deployments, and cloud synchronization is concrete, the managed boundary is understood, and the team can operate the complete system around it. Start with a production-shaped proof, constrain variation, automate safe defaults, and retain an exit path through portable data, documented configuration, and reproducible artifacts. If the service is marked preview, changing, renamed, or retired, treat availability and lifecycle constraints as first-class architecture inputs rather than documentation footnotes.

Use a short proof of architecture when uncertainty is material. Test the hardest requirement, the most important failure mode, and the expected cost driver—not another hello-world deployment. Compare AWS IoT Greengrass with the strongest alternative using the same workload and evidence. Record the decision, rejected options, assumptions, migration trigger, and date for review. Architecture remains healthy when a future team can understand both why the choice was correct and which changed fact would make it wrong.

Field note 12

A pragmatic 90-day adoption plan

Days 1–15: define the workload and responsibility map. Capture traffic or job shape, data sensitivity, availability and recovery objectives, latency, unit economics, dependencies, regional constraints, and team ownership. Build a thin threat model and request quota changes early. Select one representative path for the proof, not the easiest path. Establish a clean account, identity, network, artifact, encryption, and logging baseline before application convenience creates permanent exceptions.

Days 16–35: implement a production-shaped walking skeleton on AWS IoT Greengrass. Provision it from code, deploy an immutable artifact, integrate one real dependency, emit structured telemetry, and prove that a new team member can reproduce the environment. Exercise duplicate work, bad input, dependency timeout, and lost capacity. Measure cold and warm behavior where relevant, saturation, recovery backlog, and cost per successful business unit.

Days 36–60: harden delivery and recovery. Add policy checks, staged promotion, rollback or replacement, least-privilege runtime identity, secret rotation, data protection, retention, and symptom-based alerts. Restore from backup or recreate from artifacts in an isolated environment. Run a game day that includes an operator mistake and a compromised credential. Convert the findings into platform defaults and owned backlog items rather than a slide deck.

Days 61–90: place controlled production load on the service, review evidence with security, finance, and operations, and compare observed behavior with the original decision. Publish a paved-road module, dashboard, runbook, and exception process. Set capacity and cost review thresholds. Finally, write the exit criteria: the scale, feature, compliance need, economics, or organizational change that would trigger a move away from AWS IoT Greengrass. A reversible decision is easier to make well.

Posted in Internet of Things | Tagged: , , , , , , , , , , , | Leave a Comment »

AWS IoT FleetWise Deep Dive: Architecture, Security, Cost & Operations

Posted by Sriram Sanka on August 18, 2026

AWS IoT FleetWise architecture diagram
AWS IoT FleetWise architecture and operating-boundary overview.

AWS IoT FleetWise provides vehicle data collection campaigns, signal catalogs, and cloud ingestion. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Vehicle data collection campaigns, signal catalogs, and cloud ingestion
Primary operating unit: device, connection, message, command, job, signal, or digital-twin entity
Decision boundary: device identity, intermittent networks, fleet updates, telemetry volume, and physical safety
Field note 01

The short version

AWS IoT FleetWise provides vehicle data collection campaigns, signal catalogs, and cloud ingestion. This deep dive frames the service as an operating model: the resources it manages, the control and data paths it creates, the responsibilities that remain with customers, and the evidence required before it becomes a production dependency.

Adopt AWS IoT FleetWise when vehicle data collection campaigns, signal catalogs, and cloud ingestion is an enduring workload requirement and the managed boundary removes work your organization does not need to differentiate. The service decision should be based on measurable behavior and ownership, not catalog breadth. A proof must exercise the hardest integration, the most credible failure, the security boundary, and the dominant unit-cost driver before the design is standardized.

The practical decision is not whether AWS IoT FleetWise is powerful. It is whether its operating model fits the system and the team. It is best suited to workloads that explicitly need vehicle data collection campaigns, signal catalogs, and cloud ingestion; teams prepared to operate the surrounding identity, network, data, telemetry, delivery, and recovery controls; and platforms that can measure each device, connection, message, command, job, signal, or digital-twin entity. It is usually a poor fit for systems whose requirement can be met by a partner IoT platform or direct application messaging; teams without an accountable service owner; or designs that cannot explain device identity, intermittent networks, fleet updates, telemetry volume, and physical safety before production traffic arrives. That boundary should be written into the architecture decision so later growth does not turn an intentional choice into accidental lock-in.

Field note 02

Build the right mental model

Think of AWS IoT FleetWise as a managed control plane around each device, connection, message, command, job, signal, or digital-twin entity. The service accepts desired state, policy, configuration, or workload input, then coordinates AWS-owned infrastructure to deliver vehicle data collection campaigns, signal catalogs, and cloud ingestion. The exact managed boundary varies by feature and region, but the architectural pattern is stable: management APIs change configuration, resource policies and IAM decide who may act, service endpoints carry production work, telemetry reports selected behavior, and quotas bound how quickly the system can grow. Customer data, application correctness, access choices, downstream dependencies, and business recovery remain customer concerns even when infrastructure replacement is automated.

A production implementation begins with account and region placement, least-privilege administrative and runtime roles, network reachability, encryption ownership, quotas, logging, tags, and configuration expressed as code. For AWS IoT FleetWise, define the authoritative resource model, immutable or versioned deployment unit, and the path from a reviewed change to active service behavior. Identify asynchronous operations, eventual consistency, retry semantics, deletion behavior, and every resource created indirectly. Record which actions are safe to repeat, which require a change window, and which can cause data loss or customer-visible interruption.

Separate the control plane from the data plane in both design and incident response. The control plane creates configuration and desired state; the data plane carries production work. A deployment API succeeding does not prove that traffic, jobs, or events are healthy. Conversely, a transient control-plane problem should not automatically stop already-running work. Document which APIs are needed during steady state, which are needed only for change, and which dependencies sit on the critical request path.

Make ownership boundaries visible. Identity, network reachability, encryption keys, artifacts, telemetry, quotas, and billing dimensions frequently belong to different teams. A service can be technically managed while the surrounding system remains unmanaged. Name an owner for the application, the platform configuration, the data, the recovery procedure, and the cost model. That simple map prevents the most common failure mode in cloud programs: assuming an abstraction transferred a responsibility that it only moved.

Field note 03

Where it earns its keep

The strongest AWS IoT FleetWise architectures begin with a workload whose constraints align with the service. The following patterns are starting points, not product marketing categories. Each still needs an explicit data model, failure model, and ownership model.

Do not choose a cloud service from the deployment demo alone. A demo proves that the happy path exists; an architecture decision must explain day-two change, degraded dependencies, recovery, security evidence, and cost under real load. For AWS IoT FleetWise, those questions reveal whether the service removes undifferentiated work or merely postpones it.

  • Primary production pattern: Use AWS IoT FleetWise where vehicle data collection campaigns, signal catalogs, and cloud ingestion is on the critical path and the team can own the surrounding controls.
  • Governed shared capability: A platform team can package identity, policy, telemetry, cost allocation, and recovery defaults for multiple consumers.
  • Migration or modernization: Adopt the managed boundary incrementally while preserving data validation, rollback, and an explicit exit path.
Field note 04

Architecture moves that age well

A useful reference architecture is a set of constraints with reasons, not a diagram crowded with service icons. Start with the moves below, assign an owner to each, and encode the ones that can be enforced. Exceptions should include an expiration date and a test that proves why the normal path does not work.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

  • Define the authoritative AWS IoT FleetWise resource model and provision it from reviewed, versioned configuration.
  • Measure capacity, latency, failure, and cost per device, connection, message, command, job, signal, or digital-twin entity under production-shaped load.
  • Separate administrative, deployment, and runtime identities and centralize evidence outside the workload boundary.
  • Test restoration or replacement and document the requirement that would trigger an exit from AWS IoT FleetWise.
Field note 05

Scaling and performance

AWS IoT FleetWise capacity should be planned from the arrival rate and shape of each device, connection, message, command, job, signal, or digital-twin entity, not from an average utilization graph. Model steady load, bursts, backlog, object or payload size, concurrency, retention, dependency ceilings, and regional quotas. Separate a control-plane request being accepted from capacity becoming usable. Measure provisioning, warm-up, propagation, and recovery time. Where scaling is automatic, set guardrails that protect downstream systems and budgets. Where it is manual, define leading indicators and enough headroom for failure plus deployment overlap.

Start capacity work with a workload model rather than a product limit table. Capture arrival rate, concurrency, duration, payload size, state size, latency objective, recovery objective, and acceptable interruption. Measure percentiles and saturation, not just averages. Then test the model with production-like traffic and failure injection. Service quotas are guardrails and ceilings; they are not a substitute for understanding how a dependency behaves as demand approaches its own boundary.

Performance tuning must preserve correctness. Optimize the slowest meaningful business path, verify the change against a representative distribution, and watch for work displaced into queues, retries, caches, or operators. With AWS IoT FleetWise, a lower service-level latency can still create a worse system if downstream saturation, recovery backlog, or cost per completed transaction rises. Keep load-test artifacts and capacity assumptions versioned beside the architecture.

Field note 06

Security and governance

Secure AWS IoT FleetWise through explicit trust boundaries. Separate human administration, deployment automation, and runtime access; narrow actions and resources; use short-lived credentials; and apply organization guardrails to public exposure, deletion, cross-account sharing, and encryption changes. Protect data in transit and at rest with a documented key model. Send audit and security evidence to a boundary the workload cannot rewrite. Validate untrusted names, payloads, metadata, and configuration even when they arrive through an AWS integration. Treat service-linked roles, resource policies, grants, endpoints, and delegated administration as production code.

Use least privilege as an engineering process, not a one-time IAM document. Begin with separate human, deployment, and runtime identities. Observe required actions, narrow resources and conditions, and add explicit organization guardrails for high-impact operations. Encrypt data in transit and at rest, but also design key ownership, rotation, deletion protection, and break-glass access. Centralize audit records in an account and storage boundary that a compromised workload cannot rewrite.

Threat-model AWS IoT FleetWise across four surfaces: the management API, the workload’s runtime identity, the network and event inputs that reach it, and the software or configuration artifact that is deployed. Add the data stores and observability pipeline as separate trust boundaries. Preventive controls reduce the reachable state space; detective controls shorten time to evidence; recovery controls make destructive events survivable. A mature design has all three and tests them independently.

Governance should make the secure path faster. Provide approved modules, narrowly scoped roles, standard encryption and logging defaults, ownership tags, and automated evidence. Block dangerous configurations at the organization or pipeline boundary when the intent is unambiguous. Leave application teams enough room to tune the workload without letting every team invent identity, ingress, logging, and incident access from scratch.

Field note 07

Reliability and recovery

Reliability for AWS IoT FleetWise is the ability to preserve the intended business outcome when a zone, region, dependency, credential, quota, configuration, or operator action fails. Determine which components are regional or zonal and which state is durable, replicated, restorable, or reproducible. Set recovery-time and recovery-point objectives, then build the smallest mechanism that meets them. Test throttling, unavailable capacity, partial completion, duplicate delivery, stale configuration, corrupted input, telemetry loss, and recovery into an isolated environment. A multi-AZ service does not make a single-region or single-account application automatically recoverable.

Define failure in business terms before selecting a recovery mechanism. Availability, durability, recovery time, and recovery point are different objectives. Multi-zone placement improves some infrastructure failures but does not repair corrupt deployments or deleted data. Backups address some data events but do not guarantee a runnable application. Use layered controls: health-based replacement, redundancy, deployment rollback, data protection, quota monitoring, and a rehearsed regional or organizational recovery path where the business requires one.

Write failure-mode tests for AWS IoT FleetWise before the first serious incident. Include unavailable capacity, throttled control APIs, expired credentials, bad configuration, dependency timeout, partial deployment, telemetry loss, and operator error. Test what happens to in-flight work, how the system detects the condition, who is paged, and how replay or rollback avoids duplicate effects. Recovery time measured in a game day is more credible than recovery time copied from a diagram.

Keep the recovery path simpler than the primary path. If restoration depends on the same identity, network, artifact repository, region, or specialist that the incident removed, it is not independent. Store runbooks where responders can reach them, pre-authorize narrowly scoped emergency actions, and verify backups by restoring into an isolated environment. Record the achieved recovery point and time so business owners can compare evidence with policy.

Field note 08

Cost and capacity economics

Model AWS IoT FleetWise with a unit that finance and engineering both understand: cost per device, connection, message, command, job, signal, or digital-twin entity. Include baseline resources, request or execution charges, storage and retention, logs, network transfer, cross-zone or cross-region movement, encryption and security services, backups, support, licenses, and operator time. Build expected and stress scenarios, attach owners to long-lived resources, and alarm on abnormal unit cost. Remove waste and rightsize before purchasing commitments. Preserve the capacity and retention margins required by the reliability objective instead of treating every idle byte or spare unit as waste.

Evaluate unit economics at the level customers consume: cost per request, job, simulation, tenant, build, or environment. Tagging helps allocation, but architecture determines most spend. Include idle baseline, burst premium, storage growth, log retention, data transfer, support, licenses, and operator time. Rate discounts should follow rightsizing and workload-shape work. A commitment applied to the wrong baseline converts an optimization opportunity into a contract.

Create a cost model for AWS IoT FleetWise with a low, expected, and stress scenario. Tie every variable to a measurable workload characteristic and identify which team can influence it. Alarm on anomalous unit cost as well as total spend; total spend naturally rises with successful products, while unit cost exposes architectural drift. Review unused capacity and retained artifacts on a schedule, and give every long-lived resource an owner and lifecycle policy.

Optimization should preserve reliability margins. Removing all idle capacity, shortening every retention period, or consolidating every boundary may lower a spreadsheet while increasing incident probability and recovery time. Price the resilience requirement explicitly. Then apply the least risky lever first: eliminate waste, rightsize, improve utilization, reduce unnecessary transfer, select the correct purchasing model, and only then make longer commitments.

Field note 09

Operating it in production

Operate AWS IoT FleetWise as a product with a named owner, versioned modules, approved defaults, dashboards, runbooks, lifecycle reviews, and an exception process. Monitor customer symptoms and service saturation together. Track change success, quota headroom, access exceptions, failed operations, recovery evidence, spend, and AWS lifecycle announcements. Provide developers a paved contract that hides repetitive configuration without hiding state. Review incidents and near misses monthly until routine replacement, rollback, replay, access recertification, and recovery are boring and evidenced.

Treat configuration as versioned product code. Changes should pass static checks, policy checks, integration tests, and an environment that resembles production. Promote the same artifact; do not rebuild it differently at every stage. Prefer gradual exposure, observable health gates, and automated rollback for reversible changes. For irreversible data or identity changes, use expansion-and-contraction patterns and explicit checkpoints. Record who changed what, why, and which measured signal declared the change safe.

Build one operational view that links AWS IoT FleetWise health to customer outcomes. Infrastructure metrics explain resources, application metrics explain behavior, traces explain selected paths, and logs provide detailed evidence. None is sufficient alone. Define symptom-based alerts around availability, latency, backlog, freshness, correctness, and saturation; route them to an accountable team; and attach the first diagnostic action. Remove alerts that never change a decision.

Run a monthly service review until the platform is boring. Examine incidents, near misses, failed changes, quota headroom, runtime or image lifecycle, cost per unit, access exceptions, recovery evidence, and support announcements. Convert repeated manual actions into automation only after the team understands the decision being automated. Good operations reduce surprise without hiding state from the people accountable for it.

Field note 10

Failure patterns to avoid

Most expensive mistakes are reasonable shortcuts that survived beyond their original context. Treat these risks as design-review prompts. Ask which control detects each condition, how quickly the team can recover, and whether the workload can be moved or reshaped before the risk becomes a constraint.

A risk register is useful only when it changes action. Give each item an owner, leading indicator, mitigation, and review date. If a risk is accepted, record the business reason. If it is mitigated, test the mitigation. If it is transferred to a managed service, verify the exact responsibility that moved instead of assuming the service name moved all of it.

  • The team assumes AWS IoT FleetWise transfers application, data, or recovery responsibility that remains with the customer.
  • Automatic scale reaches a quota or overwhelms a downstream dependency before alerts explain the symptom.
  • Manual console changes create drift from the reviewed configuration and weaken incident reconstruction.
  • A lifecycle, pricing, regional, or feature change is discovered only after the architecture depends on it.
Field note 11

Alternatives and the decision

Compare AWS IoT FleetWise with a partner IoT platform or direct application messaging using the same workload, security assumptions, recovery target, and cost horizon. A managed service can reduce infrastructure labor while increasing product-specific policy, integration, and exit work. Portability of data formats or APIs does not guarantee portability of identity, monitoring, automation, or operating knowledge. The strongest decision states what AWS IoT FleetWise uniquely contributes, what the organization still owns, and which changed requirement would trigger a different platform.

AWS IoT FleetWise is a sound choice when the requirement for vehicle data collection campaigns, signal catalogs, and cloud ingestion is concrete, the managed boundary is understood, and the team can operate the complete system around it. Start with a production-shaped proof, constrain variation, automate safe defaults, and retain an exit path through portable data, documented configuration, and reproducible artifacts. If the service is marked preview, changing, renamed, or retired, treat availability and lifecycle constraints as first-class architecture inputs rather than documentation footnotes.

Use a short proof of architecture when uncertainty is material. Test the hardest requirement, the most important failure mode, and the expected cost driver—not another hello-world deployment. Compare AWS IoT FleetWise with the strongest alternative using the same workload and evidence. Record the decision, rejected options, assumptions, migration trigger, and date for review. Architecture remains healthy when a future team can understand both why the choice was correct and which changed fact would make it wrong.

Field note 12

A pragmatic 90-day adoption plan

Days 1–15: define the workload and responsibility map. Capture traffic or job shape, data sensitivity, availability and recovery objectives, latency, unit economics, dependencies, regional constraints, and team ownership. Build a thin threat model and request quota changes early. Select one representative path for the proof, not the easiest path. Establish a clean account, identity, network, artifact, encryption, and logging baseline before application convenience creates permanent exceptions.

Days 16–35: implement a production-shaped walking skeleton on AWS IoT FleetWise. Provision it from code, deploy an immutable artifact, integrate one real dependency, emit structured telemetry, and prove that a new team member can reproduce the environment. Exercise duplicate work, bad input, dependency timeout, and lost capacity. Measure cold and warm behavior where relevant, saturation, recovery backlog, and cost per successful business unit.

Days 36–60: harden delivery and recovery. Add policy checks, staged promotion, rollback or replacement, least-privilege runtime identity, secret rotation, data protection, retention, and symptom-based alerts. Restore from backup or recreate from artifacts in an isolated environment. Run a game day that includes an operator mistake and a compromised credential. Convert the findings into platform defaults and owned backlog items rather than a slide deck.

Days 61–90: place controlled production load on the service, review evidence with security, finance, and operations, and compare observed behavior with the original decision. Publish a paved-road module, dashboard, runbook, and exception process. Set capacity and cost review thresholds. Finally, write the exit criteria: the scale, feature, compliance need, economics, or organizational change that would trigger a move away from AWS IoT FleetWise. A reversible decision is easier to make well.

Posted in Internet of Things | Tagged: , , , , , , , , , , , | Leave a Comment »